CUDA and SIMT¶
Deep Dive · Digital Foundations
Optimize under a verified kernel contract.
Part of Phase 1 section 4 — C++ and Parallel Computing.
Goal: Master NVIDIA's SIMT programming model — GPU architecture, thread hierarchy, memory spaces, kernel writing, and performance optimization — so you can read and write production CUDA code and reason about hardware behavior.
Official reference: CUDA C++ Programming Guide
Compatibility reviewed 2026-10-18: the current installation documentation is CUDA13.4. Match toolkit, host compiler, operating system, driver, and GPU compute capability using the installation guide and driver compatibility rules. Record nvcc --version, the driver, and exact device model; the CUDA version displayed by nvidia-smi is not proof that that toolkit is installed. Older architecture examples below explain concepts, not a promise that every current toolkit still targets every old GPU. This Phase1 review did not execute GPU kernels; use CPU references and preserve actual device test logs when reproducing them.
1. Why GPU? — The Transistor Budget¶
CPUs emphasize low-latency execution of general-purpose work; GPUs expose many concurrent threads and high throughput for suitable parallel work. Both have caches, arithmetic units, and control logic. Their exact transistor allocation, bandwidth, core counts, and clock speeds depend on the product; a CPU core and a CUDA arithmetic lane are not equivalent units to count.
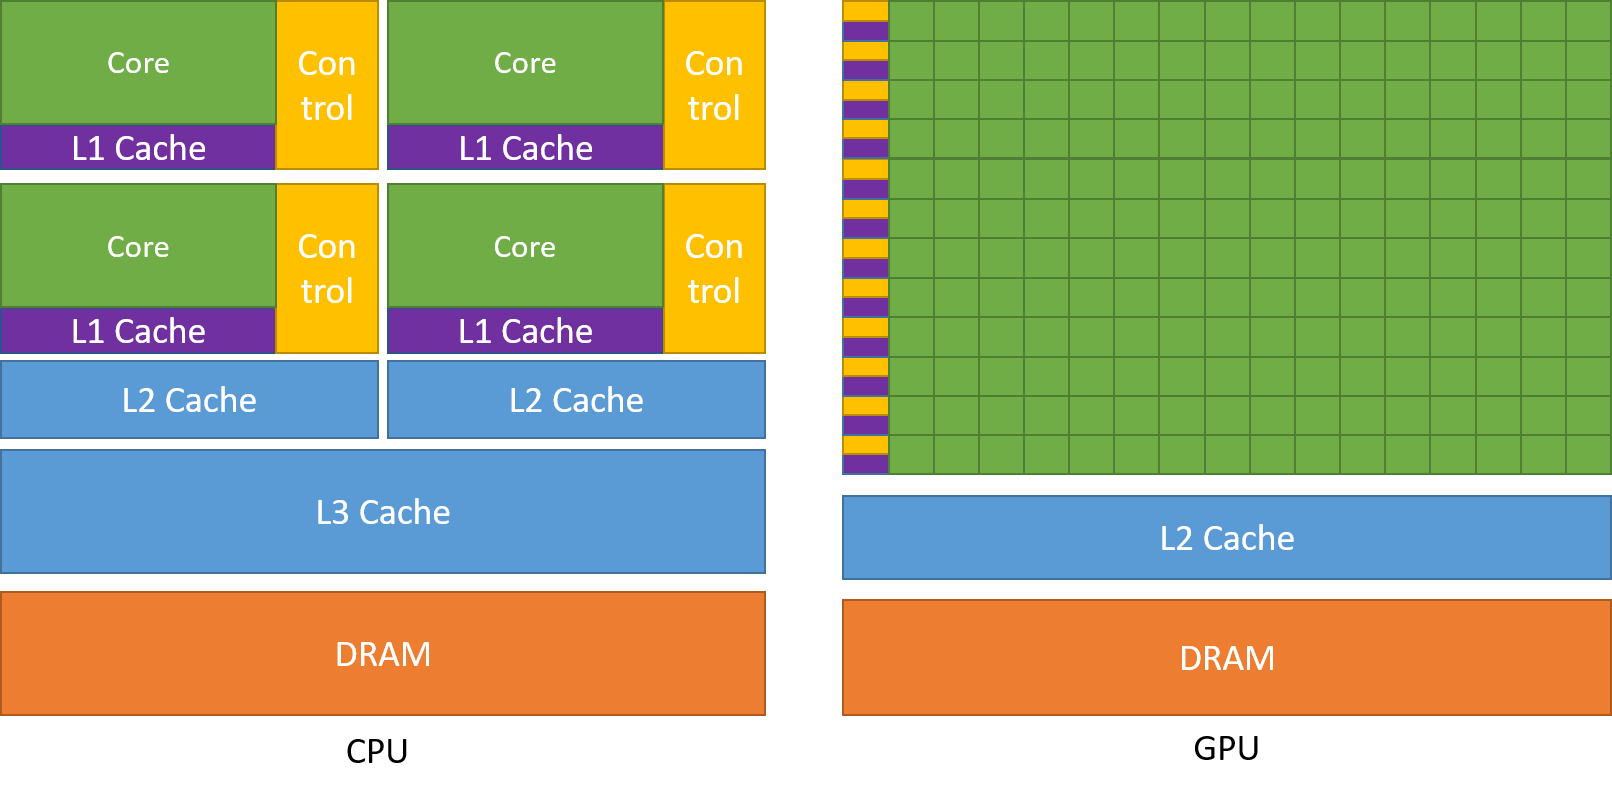
Conceptual NVIDIA illustration, not a scale drawing or current device specification.
A GPU can issue work from another ready warp while one warp waits for an operand. This requires enough eligible independent work and sufficient resources. Extra threads do not help if all of them wait on the same bottleneck, and GPUs also use caches and architecture-specific prefetch/data-movement mechanisms.
2. Heterogeneous Programming Model¶
A CUDA application always starts on the CPU (host). The host copies data to the GPU (device), launches kernels, and waits for results.
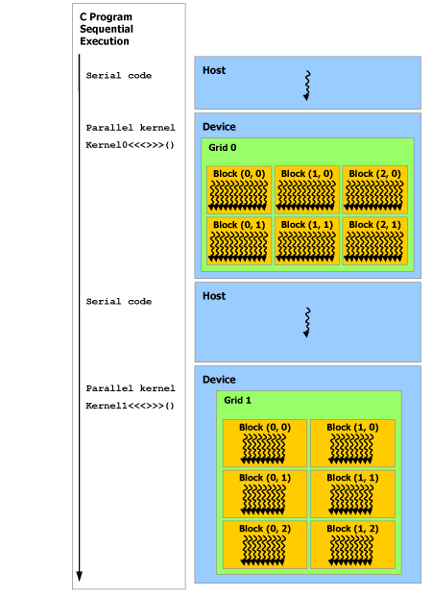
Source: NVIDIA CUDA Programming Guide
time
 │  Host (CPU)                          Device (GPU)
 │  ──────────                          ────────────
 │  Serial code runs here
 │  Allocates device memory
 │  Copies data H→D
 │  Launches kernel ──────────────────────────────────────►
 │  (async — returns immediately)                          Kernel starts
 │  Can do CPU work here                                   Grid of blocks
 │                                                         Threads execute
 │  cudaDeviceSynchronize() ─── blocks ──────────────────────────────────┐
 │                                                         Results in mem │
 ▼  Copies results D→H ◄──────────────────────────────────────────────────┘
Key rules:
- Discrete GPUs commonly have separate device memory; integrated systems such as Jetson share physical DRAM. Addressability, coherence, copies, and synchronization still depend on allocation and platform. Unified Memory is an allocation/access model, not a guarantee of zero transfers.
- Kernel launches are asynchronous — the CPU continues while the GPU works
- cudaDeviceSynchronize() blocks the CPU until all GPU work completes
3. GPU Hardware Architecture¶
3.1 The Full Chip¶
The following is a Hopper-oriented schematic. Counts and organization vary by GPU; use device properties and the matching tuning guide for limits:
GPU Die
└── GPC (Graphics Processing Cluster) × N
    └── TPC (Texture Processing Cluster) × M
        └── SM (Streaming Multiprocessor) × 2
            ├── Warp Schedulers × 4
            ├── Dispatch Units × 8
            ├── CUDA Cores (FP32) × 128
            ├── Tensor Cores × 4
            ├── Register File (256 KB)
            ├── Combined L1/shared capacity (target-specific)
            └── Load/Store Units, Special Function Units
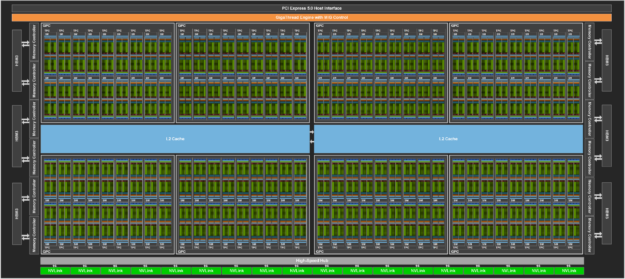
H100 full GPU — 144 SMs organized into GPCs. Source: NVIDIA Hopper Architecture
3.2 The Streaming Multiprocessor (SM)¶
An SM schedules resident thread blocks and warps. Threads in a block execute on one SM, subject to the architecture's scheduling model. A warp contains 32 threads, but independent thread scheduling means shared-memory communication still requires the appropriate explicit synchronization; “same warp” is not a memory-ordering guarantee.
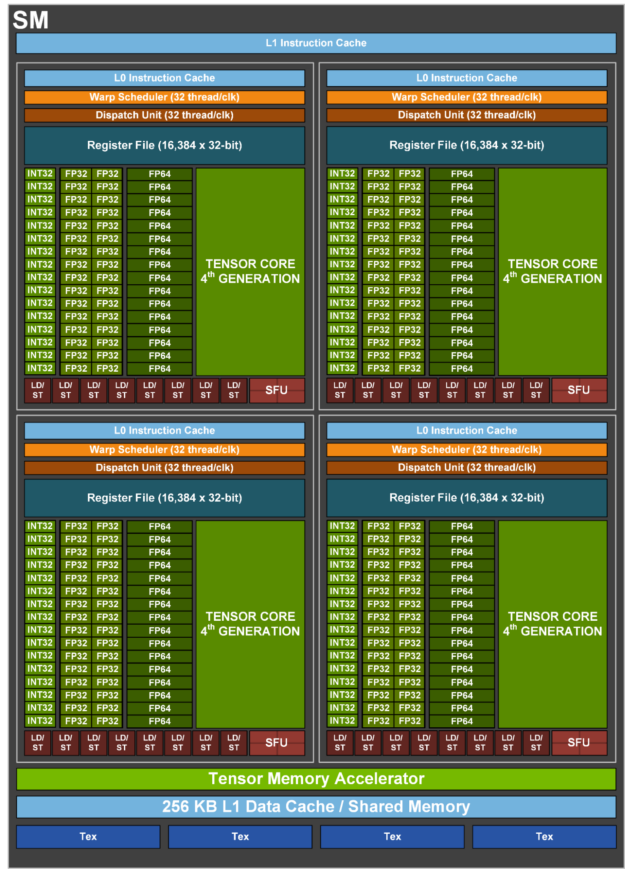
H100 SM: 4 warp schedulers, 128 FP32 CUDA cores, 4 Tensor Cores (4th gen), 256 KB register file, up to 228 KiB shared memory within a larger combined L1/shared pool. Source: NVIDIA
H100 SM components:
| Component | Count | Role |
|---|---|---|
| Warp schedulers | 4 | Each selects one ready warp per cycle |
| Dispatch units | 8 (2 per scheduler) | Issue instructions to execution units |
| FP32 CUDA cores | 128 | Floating-point arithmetic |
| INT32 units | 64 | Integer arithmetic — runs simultaneously with FP32 |
| Tensor Cores (4th gen) | 4 | Matrix multiply-accumulate (MMA) for ML |
| Register file | 256 KB | Per-thread fastest storage, compiler-allocated |
| Shared memory | Up to 228 KiB on H100 | Per-SM limit; per-block and combined L1 limits differ |
Execution pipeline — how a kernel actually runs:
kernel launch
     │
     ▼
Threads grouped into warps (32 threads each)
     │
     ▼
Warp Schedulers (×4) — each cycle, pick one ready warp
     │   A warp is "ready" when:
     │     - all operands are available
     │     - no memory stall
     │     - no data dependency
     ▼
Dispatch Units (×8) — issue 2 instructions per scheduler per cycle
     │   → 4 × 2 = up to 8 instructions issued per clock cycle
     ▼
Execution Units
     ├── FP32 cores  — floating-point ops (add, mul, fma)
     ├── INT32 units — integer ops, address calculation  ← runs in parallel with FP32
     └── Tensor Cores — MMA: D = A×B + C in one instruction
     │
     ▼
Register file (results written back per-thread)
Shared memory / L1 (for loads/stores)
Latency hiding — the core GPU performance mechanism:
GPU memory latency is ~hundreds of cycles. Instead of stalling, the scheduler instantly switches to another ready warp:
cycle:   1    2    3    ...  200   201  202
Warp 0:  [issue load] ──── stalled waiting for memory ────► [use result]
Warp 1:       [execute] [execute] [execute] ...
Warp 2:                 [execute] [execute] ...
Warp 3:                           [execute] ...
         ↑
    While warp 0 waits, warps 1–3 fill the execution units — zero idle cycles
This is why GPUs require thousands of in-flight threads: more threads = more warps = more latency hiding capacity. A kernel with too few threads leaves the SM partially idle.
FP32 + INT32 dual execution:
FP32 cores and INT32 units can issue in the same cycle. A common pattern in GPU kernels is computing a float result while simultaneously computing the next memory address:
cycle N:   FP32: result[i] = a[i] * b[i]
           INT32: next_addr = base + (i+1) * stride   ← may overlap on supported execution paths
Tensor Core operation:
Matrix instructions perform a structured tile multiply-accumulate collectively across lanes. Supported shapes and dtypes depend on the instruction and target. Count the mathematical MACs in a tile, then separately inspect instruction issue, latency, and throughput. One matrix instruction is not one cycle, and a scalar lane instruction is not a whole-warp operation.
Register file and occupancy tradeoff:
256 KB register file shared by all warps on the SM

Thread uses 32 registers:  256 KB / (32 regs × 4 B) = 2048 threads max → 64 warps
Thread uses 64 registers:  256 KB / (64 regs × 4 B) = 1024 threads max → 32 warps
Thread uses 128 registers: 256 KB / (128 regs × 4 B) = 512 threads max → 16 warps

Fewer resident warps → lower occupancy; throughput impact must be measured
The compiler balances register allocation and code generation; forcing fewer registers can add spills. Check with nvcc --ptxas-options=-v to see per-kernel register count.
Shared memory / L1 split (Hopper):
H100 shared-memory carveout: up to 228 KiB per SM; combined L1/shared pool is larger
├── Shared memory: 0 / 8 / 16 / 32 / 64 / 100 / 132 / 164 / 196 / 228 KB
└── L1 cache:      remainder

More shared memory → better for kernels with thread cooperation (matmul tiling)
More L1            → better for streaming workloads with irregular access
Use cudaFuncAttributePreferredSharedMemoryCarveout for the shared/L1 preference. cudaFuncAttributeMaxDynamicSharedMemorySize is a separate opt-in allocation limit. Check every API result and the target limits.
Common SM-level bottlenecks:
| Bottleneck | Cause | Fix |
|---|---|---|
| Warp divergence | Threads in same warp take different branches → half the units idle | Restructure code to minimize per-thread branching |
| Memory latency not hidden | Too few warps per SM (low occupancy) | Reduce registers/shared mem per thread, increase block size |
| Register pressure | Too many live variables → spill to local memory (slow) | Reduce variable scope, use __launch_bounds__ |
| Bank conflicts | Multiple threads access same shared memory bank | Pad shared arrays or stagger access patterns |
| Uncoalesced global access | Threads access non-contiguous addresses → multiple transactions | Ensure thread N accesses element N (stride-1 access) |
3.3 Resident, eligible, and issuing warps¶
A resident warp has resources allocated on an SM. An eligible warp can issue its next instruction: its required operands, execution resources, and dependencies permit progress. An issuing warp is selected for an instruction issue opportunity. These are different counts; “active warps” in occupancy metrics normally means resident work, not just the warp issuing this cycle.
A scoreboard tracks relevant dependencies. In this conceptual sequence, the second operation must wait for the first result, while another independent instruction or warp may progress:
r4 = r0 * r1      # produces r4
r5 = r4 + r2      # depends on r4
r6 = r7 + r8      # independent of that dependency, if scheduling permits
The number of schedulers, execution-pipeline widths, issue rules, cache organization, and warp-to-scheduler assignment depend on architecture. Do not infer “two instructions per scheduler per cycle” from a generic diagram or claim that adjacent FP32/INT32 instructions in SASS prove same-cycle issue. Use the target's documented throughput and measured profiler counters.
Independent integer address calculations and floating-point arithmetic may overlap on supported execution paths. They still consume issue slots, registers, and execution resources; pointer arithmetic is not free. Instruction-level parallelism can help when sufficient independent work exists, while increasing live values may raise register pressure.
A fused multiply-add evaluates a product plus addend with one final rounding, according to the selected instruction's semantics. It can differ from separately rounded multiplication and addition. Whether the compiler may contract the expression depends on language and compilation settings; correctness comparisons need an explicit tolerance or exact arithmetic contract.
3.4 Latency hiding and its limits¶
Latency is the delay until a result becomes available; throughput is the rate of completed or issued work under stated conditions. A memory access can hit a cache or travel farther through the memory system, so there is no fixed cycle cost for every “global load.” CPUs also use out-of-order execution, caches, prefetching, and sometimes hardware threads to overlap independent work. Comparing a GPU warp selection with an operating-system CPU context switch confuses different mechanisms.
Teaching example: suppose a resource permits one relevant instruction issue per cycle, and each independent chain must wait four cycles between dependent issues. Four available independent chains can potentially fill those issue opportunities. This is a simplified reasoning model, not a GPU specification. If every chain waits for the same unavailable data or the issue resource is saturated, adding chains cannot remove that bottleneck.
More resident warps can provide more eligible work. They do not guarantee progress, high utilization, or greater application throughput. Increasing occupancy by shrinking a tile may increase memory traffic; lowering register use may introduce spills. Likewise a kernel at modest occupancy can perform well if each warp has enough useful independent work.
For a real kernel, record achieved occupancy, eligible-warps/issue observations, memory throughput, stall categories, and elapsed time. Change one candidate resource choice—block size, tile size, or number of buffers—then revalidate output and compare. The occupancy API provides a useful starting configuration, not an optimum proof.
3.5 GPU Architecture Generations¶
These are selected examples, not a device-support matrix. Use NVIDIA’s compute-capability table and the Vera Rubin platform description to distinguish GPU architecture, CPU name, and CUDA support.
| Generation | Architecture | Compute Cap | Key Feature | Example GPU |
|---|---|---|---|---|
| 2017 | Volta | 7.0 | Tensor Cores (1st gen), Independent Thread Scheduling | V100 |
| 2018 | Turing | 7.5 | RT Cores, INT8/INT4 Tensor Cores | RTX 2080 |
| 2020 | Ampere | 8.0 / 8.6 | 3rd gen Tensor Cores, TF32, BF16, MIG, sparsity | A100, RTX 3090 |
| 2022 | Hopper | 9.0 | 4th gen Tensor Cores, TMA, Thread Block Clusters, FP8, Transformer Engine | H100 |
| 2024 | Blackwell | 10.x | 5th gen Tensor Cores, FP4, NVLink 5, confidential compute | B100, B200 |
| 2026 platform example | Rubin GPU / Vera CPU | Query the exact GPU and supported CUDA toolchain | Vera names the CPU; Rubin names the GPU | Vera Rubin platform |
4. Thread Hierarchy¶
CUDA organizes threads in a 3-level hierarchy: Grid → Block → Thread, with warps as an implicit hardware grouping of 32 threads.
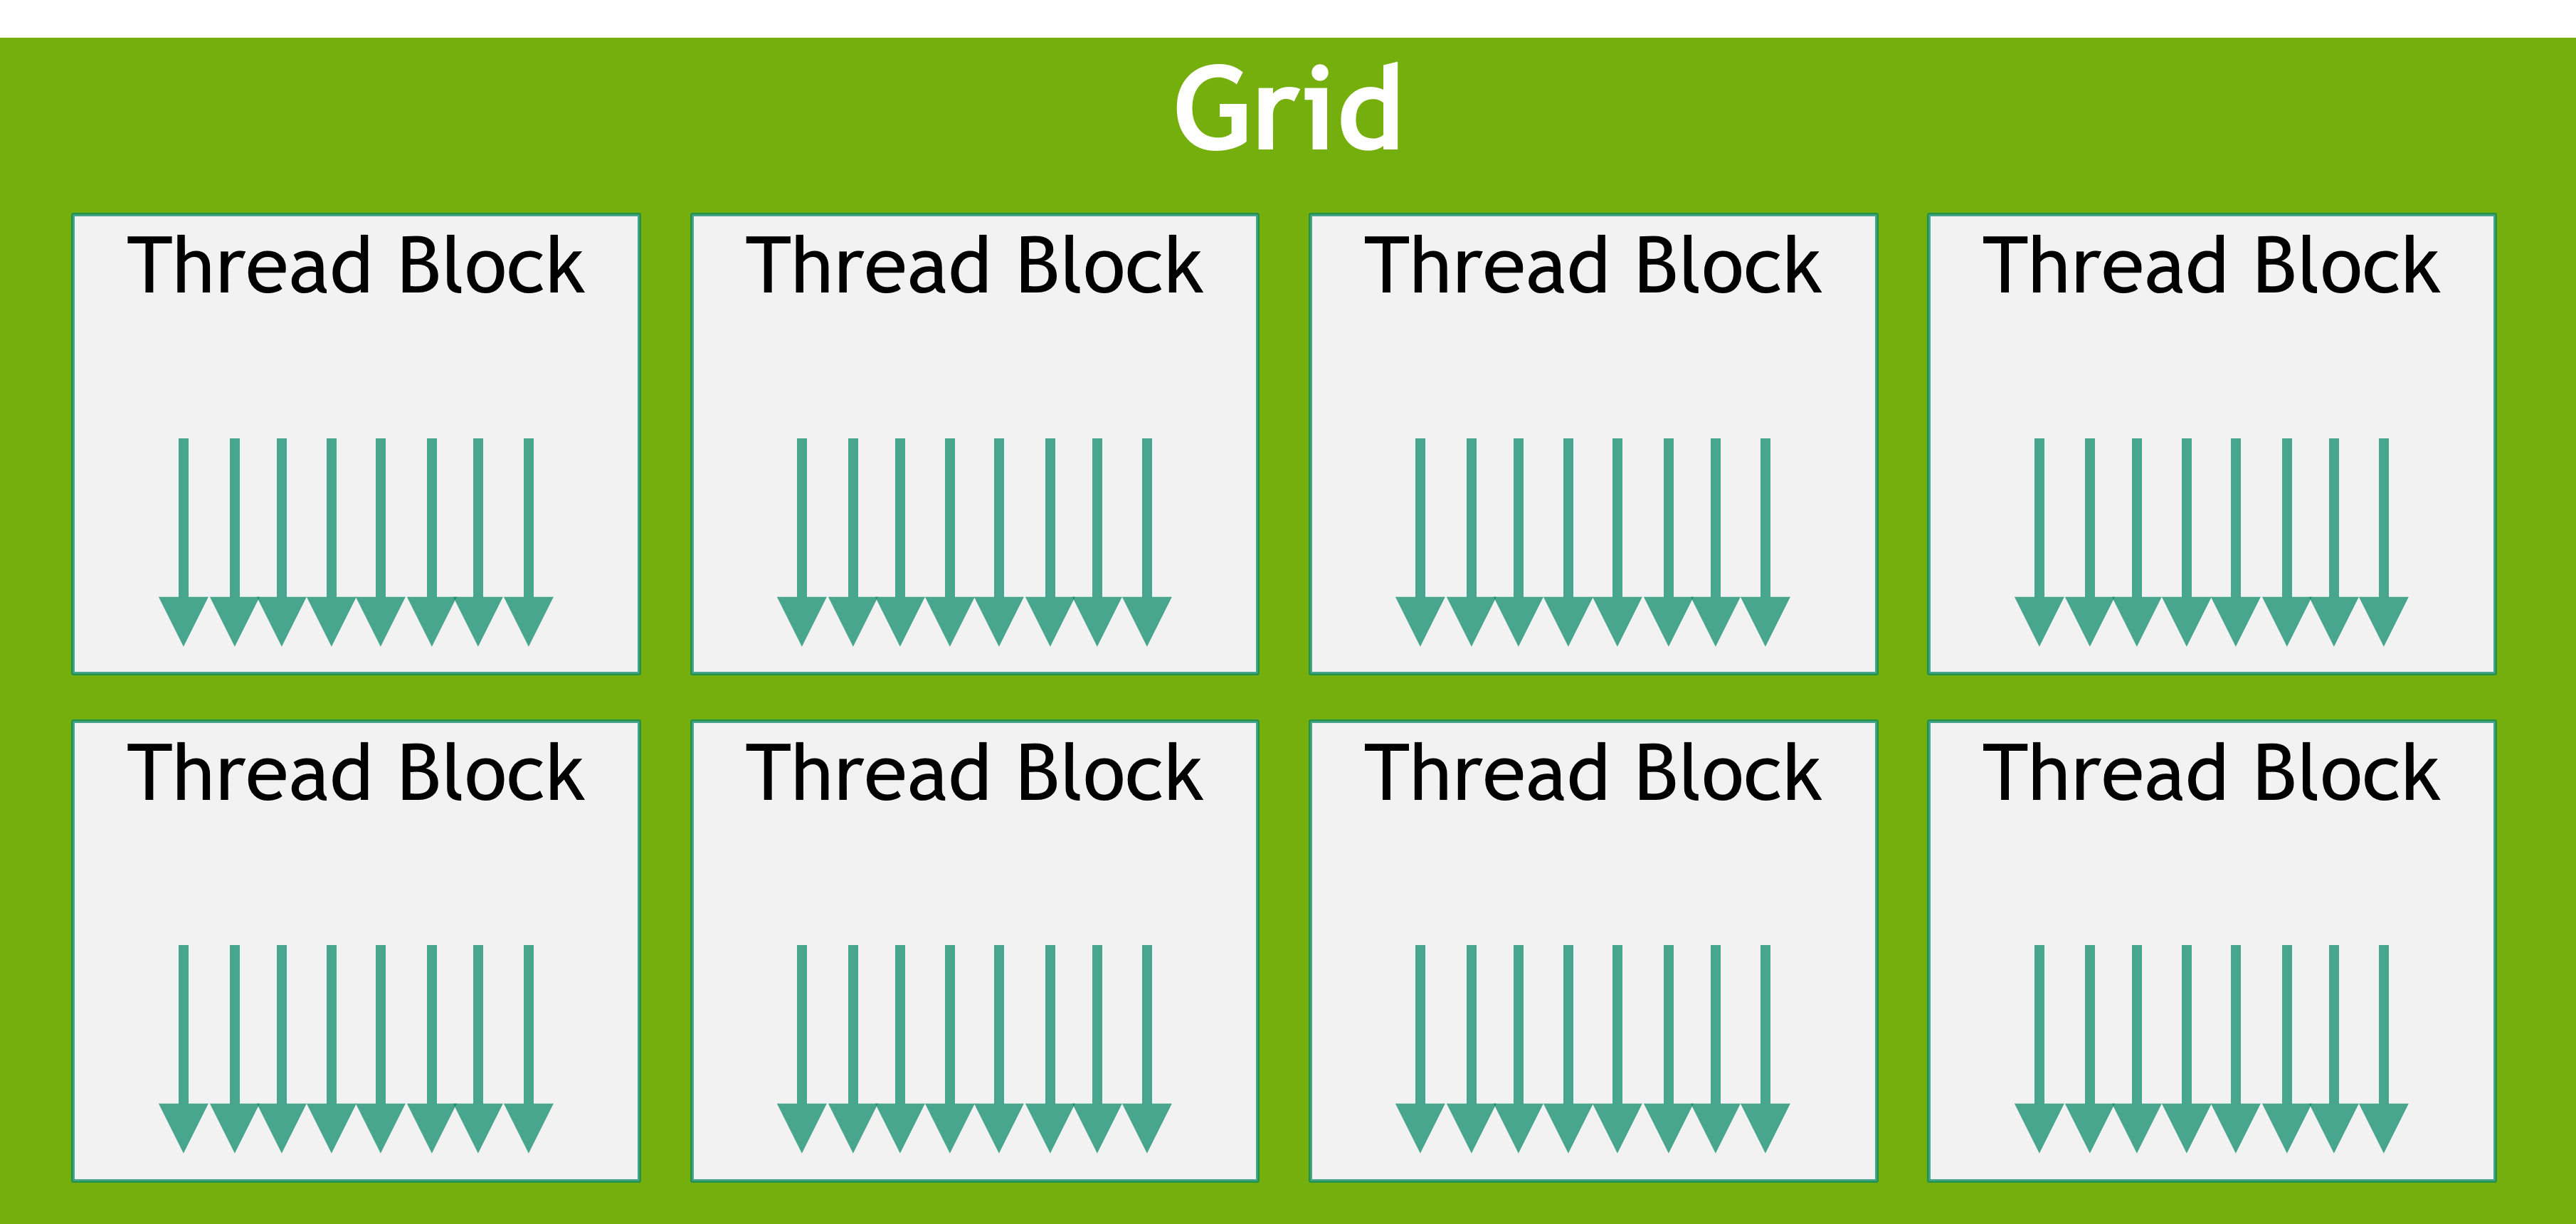
Source: NVIDIA CUDA Programming Guide
4.1 Grid, Block, Warp, Thread¶
Grid  (one per kernel launch)
├── Block (0,0)  ── 1024 threads max ── runs on one SM
│   ├── Warp 0   ── threads 0-31
│   ├── Warp 1   ── threads 32-63
│   └── Warp 31  ── threads 992-1023
├── Block (1,0)
├── Block (0,1)
└── ...
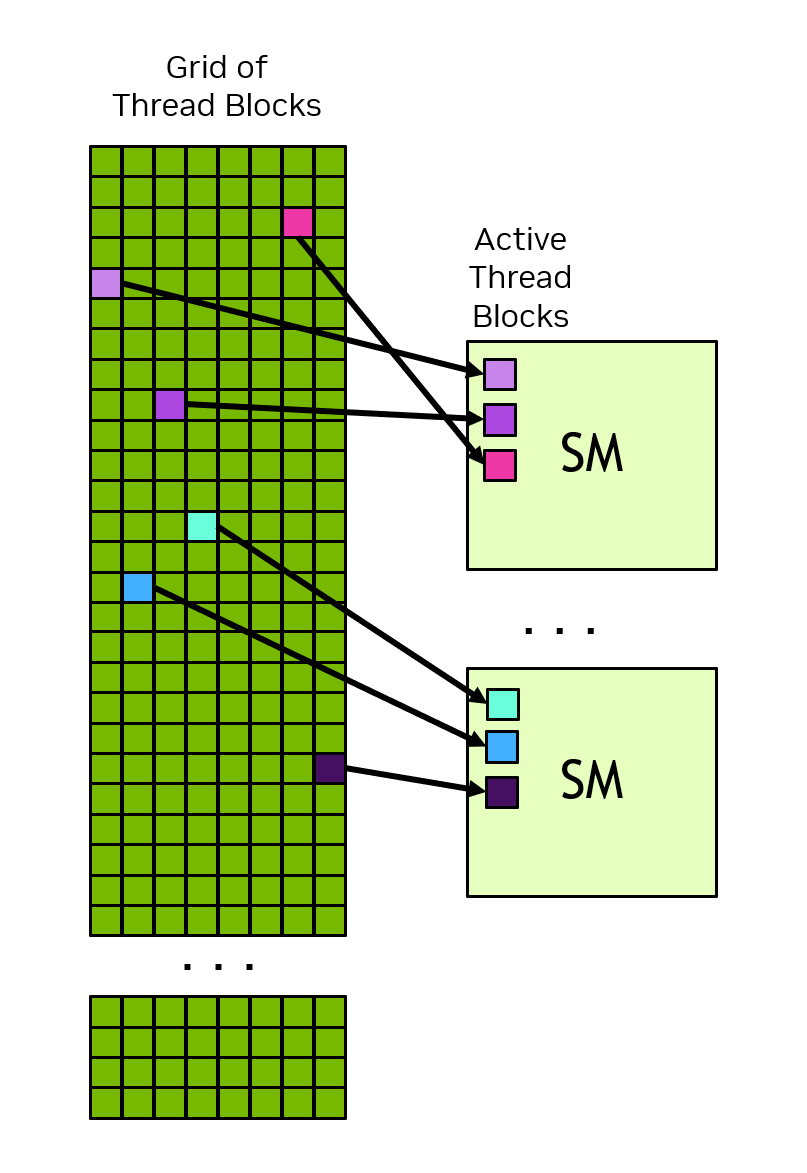
Thread blocks are dispatched to SMs. Multiple blocks can reside on one SM simultaneously (limited by registers, shared memory, and SM capacity). Source: NVIDIA
Built-in variables every kernel sees:
| Variable | Type | Meaning |
|---|---|---|
threadIdx.x/y/z |
uint3 |
Thread index within its block |
blockIdx.x/y/z |
uint3 |
Block index within the grid |
blockDim.x/y/z |
uint3 |
Block dimensions (total threads per block) |
gridDim.x/y/z |
uint3 |
Grid dimensions (total blocks) |
warpSize |
int |
Always 32 |
Compute a global 1D thread ID:
Compute a global 2D thread ID:
4.2 Constraints and Limits¶
Max threads per block:      1024
Max blocks per grid (x):    2,147,483,647
Max shared memory per block: query device/function; H100 opt-in limit is 227 KiB
Max registers per thread:   255
Warp size:                  32  (always)
Block size rule of thumb:
- Must be a multiple of 32 (warp size) — avoid partial warps
- 128, 256, or 512 are common choices
- Use cudaOccupancyMaxPotentialBlockSize() to obtain an occupancy-based starting point, then measure candidate sizes
4.3 Thread Block Clusters (Compute Capability 9.0+ / Hopper)¶
Hopper adds a new level between grid and block: clusters — a group of thread blocks that are guaranteed to run on SMs within one GPC concurrently and can cooperate directly.
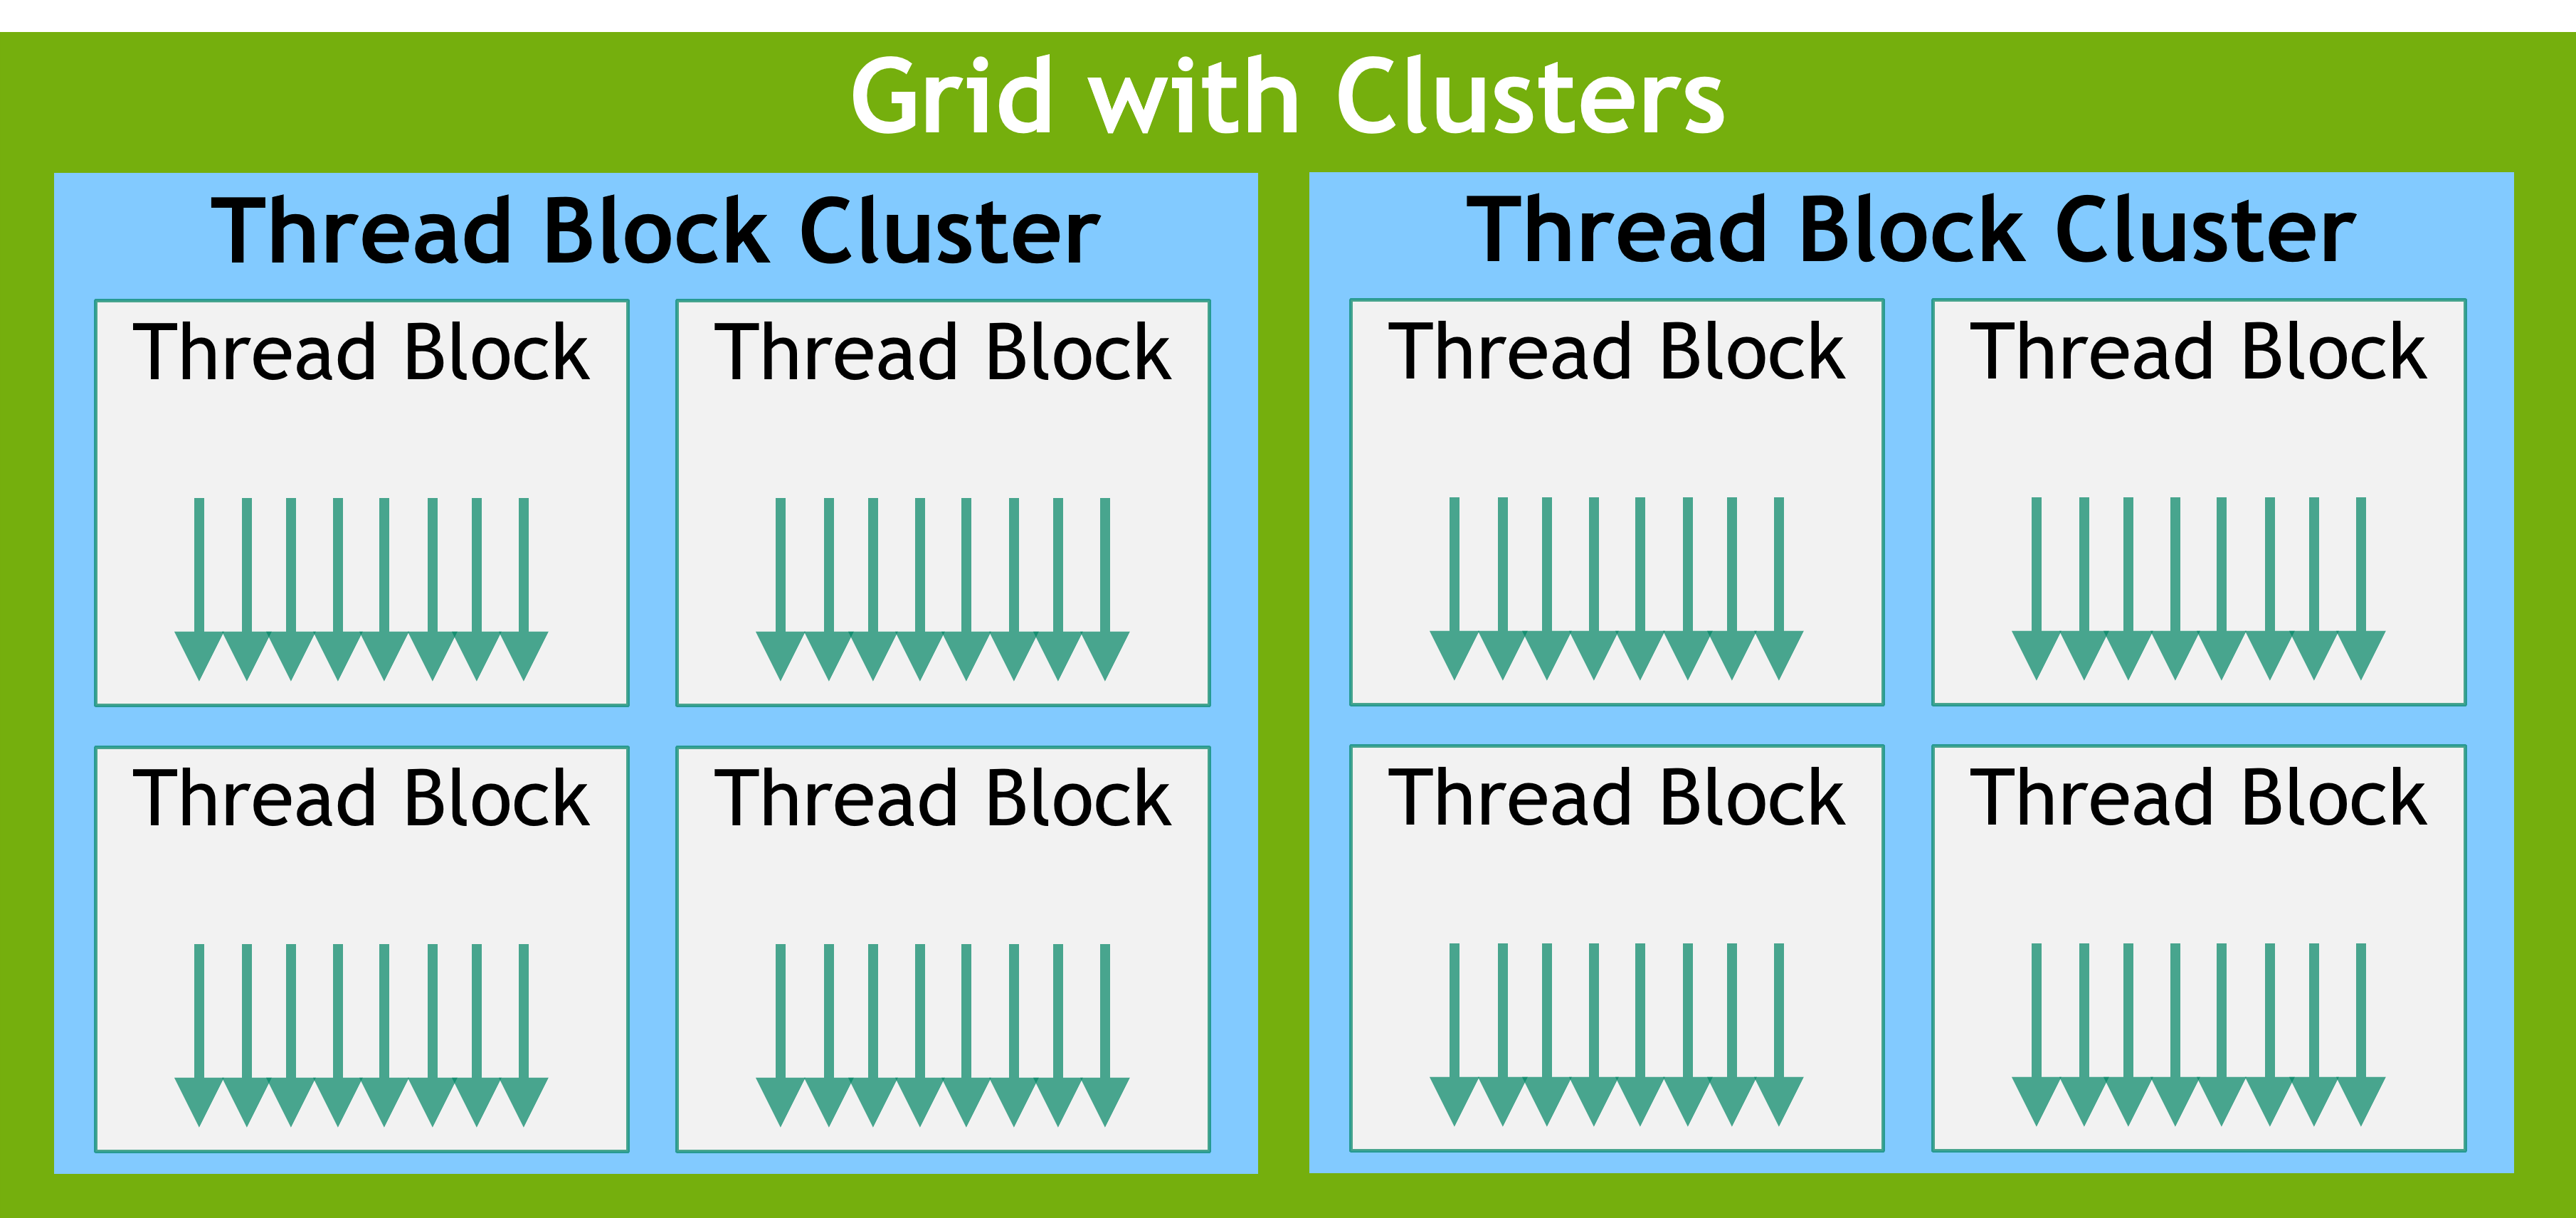
Thread Block Clusters: multiple blocks scheduled simultaneously on the same GPC, sharing distributed shared memory. Source: NVIDIA
Before clusters — blocks are independent:
Grid
├── Block 0 → SM 5   (wherever the scheduler puts it)
├── Block 1 → SM 71  (no control over placement)
├── Block 2 → SM 12
└── Block 3 → SM 99
Communication between independent blocks: use a supported global-memory protocol ❌
Synchronization between blocks: impossible without kernel relaunch ❌
With clusters — blocks form coordinated teams:
Grid
├── Cluster 0
│   ├── Block 0 → SM 0  ← guaranteed on neighbouring SMs
│   ├── Block 1 → SM 1  ← can share memory directly
│   ├── Block 2 → SM 2  ← can synchronize
│   └── Block 3 → SM 3
├── Cluster 1
│   ├── Block 4 → SM 4
│   └── ...
Three new capabilities:
| Capability | Before clusters | With clusters |
|---|---|---|
| Cross-block sync | Impossible | cluster.sync() barrier |
| Cross-block memory | Global-memory communication with explicit ordering | Cluster-scoped distributed shared memory |
| Co-scheduling | No guarantee | Co-scheduled within one GPC |
Launching with Clusters¶
// Hopper cluster launch (compute capability 9.0+)
__global__ void __cluster_dims__(2, 1, 1) my_kernel(float* data) {
    // This kernel runs with 2 blocks per cluster
    // Access cluster info:
    namespace cg = cooperative_groups;
    auto cluster = cg::this_cluster();

    unsigned int cluster_rank = cluster.block_rank();  // 0 or 1 in this cluster
    unsigned int cluster_size = cluster.num_blocks();   // 2

    // ... do work ...

    // Synchronize all blocks in the cluster
    cluster.sync();  // ← impossible without clusters!
}

// Alternative: runtime configuration
cudaLaunchConfig_t config = {};
config.gridDim = grid;
config.blockDim = block;

cudaLaunchAttribute attr;
attr.id = cudaLaunchAttributeClusterDimension;
attr.val.clusterDim = {2, 1, 1};   // 2 blocks per cluster
config.attrs = &attr;
config.numAttrs = 1;

cudaLaunchKernelEx(&config, my_kernel, args...);
Distributed Shared Memory (DSM)¶
A thread block cluster can access the shared-memory allocations of its member blocks. Each allocation still belongs to a block. Remote accesses must occur while the owning block exists, so synchronize before remote use and again before blocks exit or reuse storage.
// Structural sketch: provide includes, TILE_SIZE, load_tile, output, and checks.
__global__ void __cluster_dims__(4, 1, 1) dsm_kernel(float* data, float* output) {
    auto cluster = cooperative_groups::this_cluster();
    __shared__ float tile[TILE_SIZE];
    load_tile(tile, data, blockIdx.x);
    cluster.sync();
    unsigned target = (cluster.block_rank() + 1) % cluster.num_blocks();
    float* remote = cluster.map_shared_rank(tile, target);
    if (threadIdx.x < TILE_SIZE)
        output[blockIdx.x * TILE_SIZE + threadIdx.x] = remote[threadIdx.x];
    cluster.sync();  // no owner exits while another block still reads its tile
}
Capacity is the sum of actual legal per-block allocations, not the advertised maximum shared-memory capacity per SM multiplied blindly by block count. For example, four blocks each allocating 16 KiB expose 64 KiB in total. This does not make every access local or guarantee faster execution than a cache-friendly global-memory alternative.
The portable maximum cluster size is eight where supported; device or MIG constraints can reduce availability. H100 supports a nonportable opt-in size of 16. Use cluster occupancy queries for the actual launch. Larger clusters can reduce concurrent work. No cluster size or fixed DSM/global latency ratio is universally optimal. Hopper tuning guide.
4.4 Tiling — The Universal GPU Optimization¶
Tiling is useful when it exposes data reuse or a suitable hardware work shape. It also consumes registers/shared memory and adds boundary and synchronization work. Measure the tradeoff for the operation.
The core idea: break a large problem into small tiles that fit in fast on-chip memory (shared memory / registers), compute on each tile, then move to the next.
Without tiling:                          With tiling:

  For each output element:                For each tile:
    Read inputs from global memory          Load tile into shared memory (1 read)
    Compute                                 Compute on tile (many reuses)
    Write output to global memory           Load next tile
                                            Write final output (1 write)
  Every element = separate DRAM access
  = SLOW                                  Each value loaded once, used many times
                                          = FAST
Why it works — data reuse:
Tiled matmul: C = A × B,  tile size T = 16

Without tiling:
  Each C[i,j] reads A[i, 0..N] and B[0..N, j] from DRAM
  Total logical input loads: 2 × N per output element
  For N=4096: 8192 DRAM reads per element ❌

With tiling:
  Load 16×16 tile of A into shared memory → reused by 16 threads
  Load 16×16 tile of B into shared memory → reused by 16 threads
  Logical input loads per output: 2 × N/T = 2 × 4096/16 = 512
  That's 16× fewer logical input loads ✓

  With T=32:  32× fewer logical input loads than this naive baseline
  With T=64:  64× fewer logical input loads, if the tile is legal and fits
Thread block = tile:
One thread block handles one output tile.
Threads cooperatively load data into shared memory.
Each thread computes one element of the output tile.

Block (16×16 = 256 threads)
  ├── Threads 0–15:   load row 0 of tile A, row 0 of tile B
  ├── Threads 16–31:  load row 1...
  ├── ...
  └── __syncthreads() → all data in shared memory → compute
This is why block size, shared memory size, and tile size are so tightly coupled.
Tiling hierarchy on modern GPUs:
Level 0: Register tiling
  Each thread holds a small tile (e.g., 4×4) in registers
  Finite registers; instruction dependencies and register pressure still cost time
  Used by: CUTLASS, cuBLAS inner loops

Level 1: Shared memory tiling (per block)
  Thread block loads a tile into shared memory; capacity depends on the target
  Access cost depends on instructions, conflicts, and architecture
  Used by: standard tiled matmul, FlashAttention

Level 2: Distributed shared memory tiling (per cluster, Hopper)
  Cluster blocks can access distributed shared memory on supported devices
  Requires the appropriate cluster lifetime and synchronization contract
  Used by: Hopper-optimized FlashAttention, large attention tiles

Level 3: L2 cache tiling
  Multiple blocks' access patterns can reuse data through L2
  Capacity, latency, and contention depend on the device and workload
  Used by: persistent kernels, stream-K GEMM
4.5 Tiling for AI Workloads¶
Every AI operation maps to a tiled computation. Understanding this mapping is the bridge from CUDA programming to AI accelerator design.
Matrix Multiply (GEMM) — The Foundation¶
C[M×N] = A[M×K] × B[K×N]

Tile: each block computes a TILE_M × TILE_N output tile

  ┌────────────────────┐         ┌────────────────────┐
  │ A                  │         │ B                  │
  │ ┌──────┐           │         │ ┌──────┐           │
  │ │Tile A│→ load to  │         │ │Tile B│→ load to  │
  │ │TILE_M│  shared   │         │ │TILE_K│  shared   │
  │ │×     │  memory   │         │ │×     │  memory   │
  │ │TILE_K│           │         │ │TILE_N│           │
  │ └──────┘           │         │ └──────┘           │
  └────────────────────┘         └────────────────────┘

  Output: C[TILE_M × TILE_N] = Σ_k (TileA × TileB)

  Iterate over K dimension in chunks of TILE_K.
  Each iteration: 1 load from DRAM, many multiplies from shared memory.
Optimized GEMM libraries use architecture-specific schedules, layouts, and instructions. Double buffering, register tiling, and matrix instructions are common choices, but their shapes and interfaces are not fixed to this teaching example.
Attention — FlashAttention Tiling¶
Attention is the bottleneck of every transformer. FlashAttention solves it with tiling:
Standard attention (materializes full matrix):

  S = Q × K^T           (seq × seq matrix — huge!)
  P = softmax(S)         (still seq × seq)
  O = P × V              (output)

  Memory: O(seq²) — for seq=4096, that's 64 MB in FP16
  Problem: doesn't fit in shared memory, tons of DRAM traffic

FlashAttention (tiled, never materializes full matrix):

  For each Q tile (TILE_Q rows of Q):
    For each K/V tile (TILE_KV columns of K, rows of V):
      Load Q tile into shared memory
      Load K tile into shared memory
      S_tile = Q_tile × K_tile^T           (small: TILE_Q × TILE_KV)
      P_tile = online_softmax(S_tile)       (computed incrementally!)
      Load V tile into shared memory
      O_tile += P_tile × V_tile            (accumulate in registers)
    Write O_tile to global memory

  Memory: O(seq) — only tiles in shared memory at any time
  Traffic reduction depends on sequence length, head dimension, tiling, and baseline
FlashAttention data flow through memory:

  Global memory (HBM)
        │
        ├── Load Q tile ──────►  Shared memory
        ├── Load K tile ──────►  Shared memory
        │                            │
        │                       Compute S = Q × K^T
        │                       (stays in registers)
        │                            │
        │                       Compute softmax(S)
        │                       (online, incremental)
        │                            │
        ├── Load V tile ──────►  Shared memory
        │                            │
        │                       Compute O += P × V
        │                       (accumulate in registers)
        │                            │
        └── Write O tile ◄──── Registers
                                (only final output touches DRAM)
Why this matters on Jetson: Avoiding materialized attention matrices can reduce traffic to shared LPDDR. The benefit depends on sequence length, head dimension, kernel support, and power mode; a traffic reduction does not translate automatically into the same latency speedup. Compare an available fused implementation against a correct baseline on the exact board.
Convolution — im2col + GEMM Tiling¶
CNNs use the same tiling through a clever trick: im2col converts convolution into matrix multiplication, then cuBLAS tiled GEMM handles it:
Input image: [batch × channels × height × width]
Kernel: [out_channels × in_channels × kH × kW]

im2col: unfold image patches into a matrix
  Each patch (kH × kW × channels) becomes one column
  Result: [patch_size × num_patches] matrix

Now: convolution = matrix multiply (patches × kernels)
  → cuBLAS tiled GEMM → Tensor Cores → maximum throughput
Tensor Parallelism — Tiling Across GPUs¶
For models too large for one GPU (or one Jetson), tensor parallelism splits weight matrices across devices:
Single GPU:
  Y = X × W                    (W is too large for one GPU)

Tensor parallel (4 GPUs):
  W split column-wise: W = [W₀ | W₁ | W₂ | W₃]

  GPU 0: Y₀ = X × W₀
  GPU 1: Y₁ = X × W₁          ← each GPU computes partial output
  GPU 2: Y₂ = X × W₂
  GPU 3: Y₃ = X × W₃

  All-gather: Y = [Y₀ | Y₁ | Y₂ | Y₃]   ← combine over NVLink/PCIe
On Jetson, tensor parallelism isn't applicable (single GPU), but the concept maps directly to the GPU+DLA split:
Jetson "parallelism":
  DLA: runs conv/pool layers (subset of model)
  GPU: runs attention/custom layers

  Same output buffer shared via unified memory — zero-copy handoff
  Both engines consume bandwidth from the same 51 GB/s pipe
Clusters and attention: an implementation question¶
Distributed shared memory may enable cross-block cooperation, but a larger aggregate allocation alone does not produce a valid attention kernel. Define which block owns each Q/K/V tile, when transfers complete, where online-softmax state lives, and which barriers protect reuse. Include accumulator and normalization state in the budget. A fourfold tile dimension does not imply fourfold lower traffic or latency.
Start with a validated supported attention library and measure its complete operation. Treat a cluster-based redesign as an experiment requiring a reference, tail tests, race checks, resource accounting, and profiling.
4.6 The Tiling Mental Model¶
Level              Unit            Fast memory        Tile size
──────────────────────────────────────────────────────────────────
Thread             registers       registers          2×2 – 8×8
Warp               warp shuffles   register file      32-wide
Block              thread block    shared memory      16×16 – 64×64
Cluster (Hopper)   block cluster   distributed SM     64×64 – 256×256
SM array           all SMs         L2 cache           entire matrix dimension
Multi-GPU          GPUs            NVLink/PCIe        tensor parallel split

Each level follows the same principle:
  1. Load data into the fast memory at this level
  2. Reuse it as many times as possible
  3. Only go to the next (slower) level when this level is exhausted
4.7 Work a tiled matmul budget correctly¶
Consider a teaching schedule, not an observed cycle trace: one block of 256 threads computes a 128×128 output tile, processing K in chunks of 32. A/B elements are two bytes and accumulators are four bytes.
The staged A and B tiles need 128*32*2 + 32*128*2 = 16,384 bytes. The output contains 16,384 accumulators, or 65,536 bytes. If distributed evenly over 256 threads, that is 64 accumulators per thread, before operands, pointers, and loop state. A claim of 16 accumulators per thread would cover only a quarter of this output tile. The compiler may use registers, spills, or a different mapping; inspect its resource report.
There are eight warps. An abstract partition into eight 32×64 output regions covers the 128×128 tile. A 64×32 region would also have 2,048 outputs, but the physical arrangement must cover the tile without gaps or overlap. A matrix-instruction implementation uses the documented fragment/lane mapping; it is not necessarily a rectangular private array per thread.
For one K chunk, mathematical work is 128*128*32 = 524,288 MACs. With a convention of two operations per MAC that is 1,048,576 operations. Neither count states how many instructions or cycles execute. A fixed matrix instruction must be counted with its own supported dimensions, precision, and issue behavior.
A correct staged implementation performs these steps:
- Cooperatively load the A/B tiles with valid bounds; zero-pad the final K chunk if necessary.
- Establish completion and block-wide visibility before using shared operands.
- Accumulate into the existing C partial sums.
- Synchronize before overwriting shared operands still being read.
- Repeat over the complete K dimension, then store each valid C element once.
For a two-buffer pipeline, A/B staging grows from 16 KiB to 32 KiB. Overlap requires a supported asynchronous copy path and explicit completion tracking. It can hide some latency when computation and transfer durations allow it; it does not guarantee a busy SM or hide every stall. Increased shared memory can also reduce resident blocks.
For CPU-executable practice with exact traffic counts, ragged shapes, and a clearly defined cycle model, use the tiling and dataflow lab. Its systolic model is a different architecture, but the shape, storage, and arithmetic checks transfer directly.
5. Writing Kernels¶
5.1 Function Qualifiers¶
// Runs on GPU, called from CPU (kernel)
__global__ void my_kernel(float* a, float* b, float* c, int N);

// Runs on GPU, called from GPU only
__device__ float helper(float x);

// Runs on CPU (default)
void host_function();

// Compiles for both CPU and GPU
__host__ __device__ float clamp(float x, float lo, float hi) {
    return x < lo ? lo : (x > hi ? hi : x);
}
5.2 Launching a Kernel¶
// Syntax: kernel<<<grid_dim, block_dim, shared_mem_bytes, stream>>>(args)

int N = 1 << 20;   // 1M elements
int block_size = 256;
int grid_size = (N + block_size - 1) / block_size;  // ceil division

saxpy<<<grid_size, block_size>>>(a, b, c, N);

// 2D launch for matrix ops
dim3 block(16, 16);         // 256 threads per block
dim3 grid((W + 15) / 16, (H + 15) / 16);

matmul<<<grid, block>>>(A, B, C, M, N, K);
5.3 Complete checked SAXPY example¶
Use the checked-in saxpy.cu. It computes c[i] = 2*a[i] + b[i] and compares every element against a host reference. The input values are small integer-valued floats, so exact equality is appropriate for this particular fixture. General floating-point workloads need a justified tolerance.
The program covers lengths 0,1,31,32,33,255,256,257,1025. The empty case returns without allocation/launch; the final partial block uses an i<n guard. Every runtime call, the launch status, and the completion boundary are checked. A mismatch exits with failure; it never prints “OK” after a failed value check.
# From this CUDA and SIMT directory; choose the architecture of your device.
nvcc -std=c++17 -O2 -arch=sm_80 labs/saxpy.cu -o /tmp/course-saxpy
/tmp/course-saxpy
Executed evidence: the translation unit was compiled to an object for sm_80 with nvcc 13.4.92 on 2026-10-18. No GPU was available for execution, so the nine runtime cases are supplied for reproduction, not reported as passed here. The OpenCL CPU lab provides a heterogeneous kernel that was actually executed on this course-review host.
__global__ void saxpy(float alpha, const float* a, const float* b, float* c, int n) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < n) c[i] = alpha * a[i] + b[i];
}
For n=257 and 256 threads/block, the launch needs two blocks. Only thread 0 of the second block computes a valid output. The remaining threads must avoid the memory access; allocating a larger output alone would not make out-of-range input reads valid.
5.4 Error Checking¶
// Macro to check any CUDA call
#define CUDA_CHECK(call) do {                                    \
    cudaError_t err = (call);                                    \
    if (err != cudaSuccess) {                                    \
        fprintf(stderr, "CUDA error at %s:%d — %s\n",           \
                __FILE__, __LINE__, cudaGetErrorString(err));    \
        exit(1);                                                 \
    }                                                            \
} while(0)

// Usage
CUDA_CHECK(cudaMalloc(&d_a, bytes));
CUDA_CHECK(cudaMemcpy(d_a, h_a, bytes, cudaMemcpyHostToDevice));

// Check kernel errors (kernels don't return error codes)
my_kernel<<<grid, block>>>(args);
CUDA_CHECK(cudaGetLastError());       // check launch error
CUDA_CHECK(cudaDeviceSynchronize());  // wait + check execution error
Check both launch and completion errors.
cudaGetLastError()can detect a launch-configuration failure; asynchronous execution failures may surface later. Synchronize at the point where the application actually needs completion, using a stream/event or another appropriate checked completion operation. Removing all completion/error checks is not a production optimization.
6. Memory Spaces¶
Every variable in CUDA lives in a specific memory space. Understanding this is the most important skill for optimization.
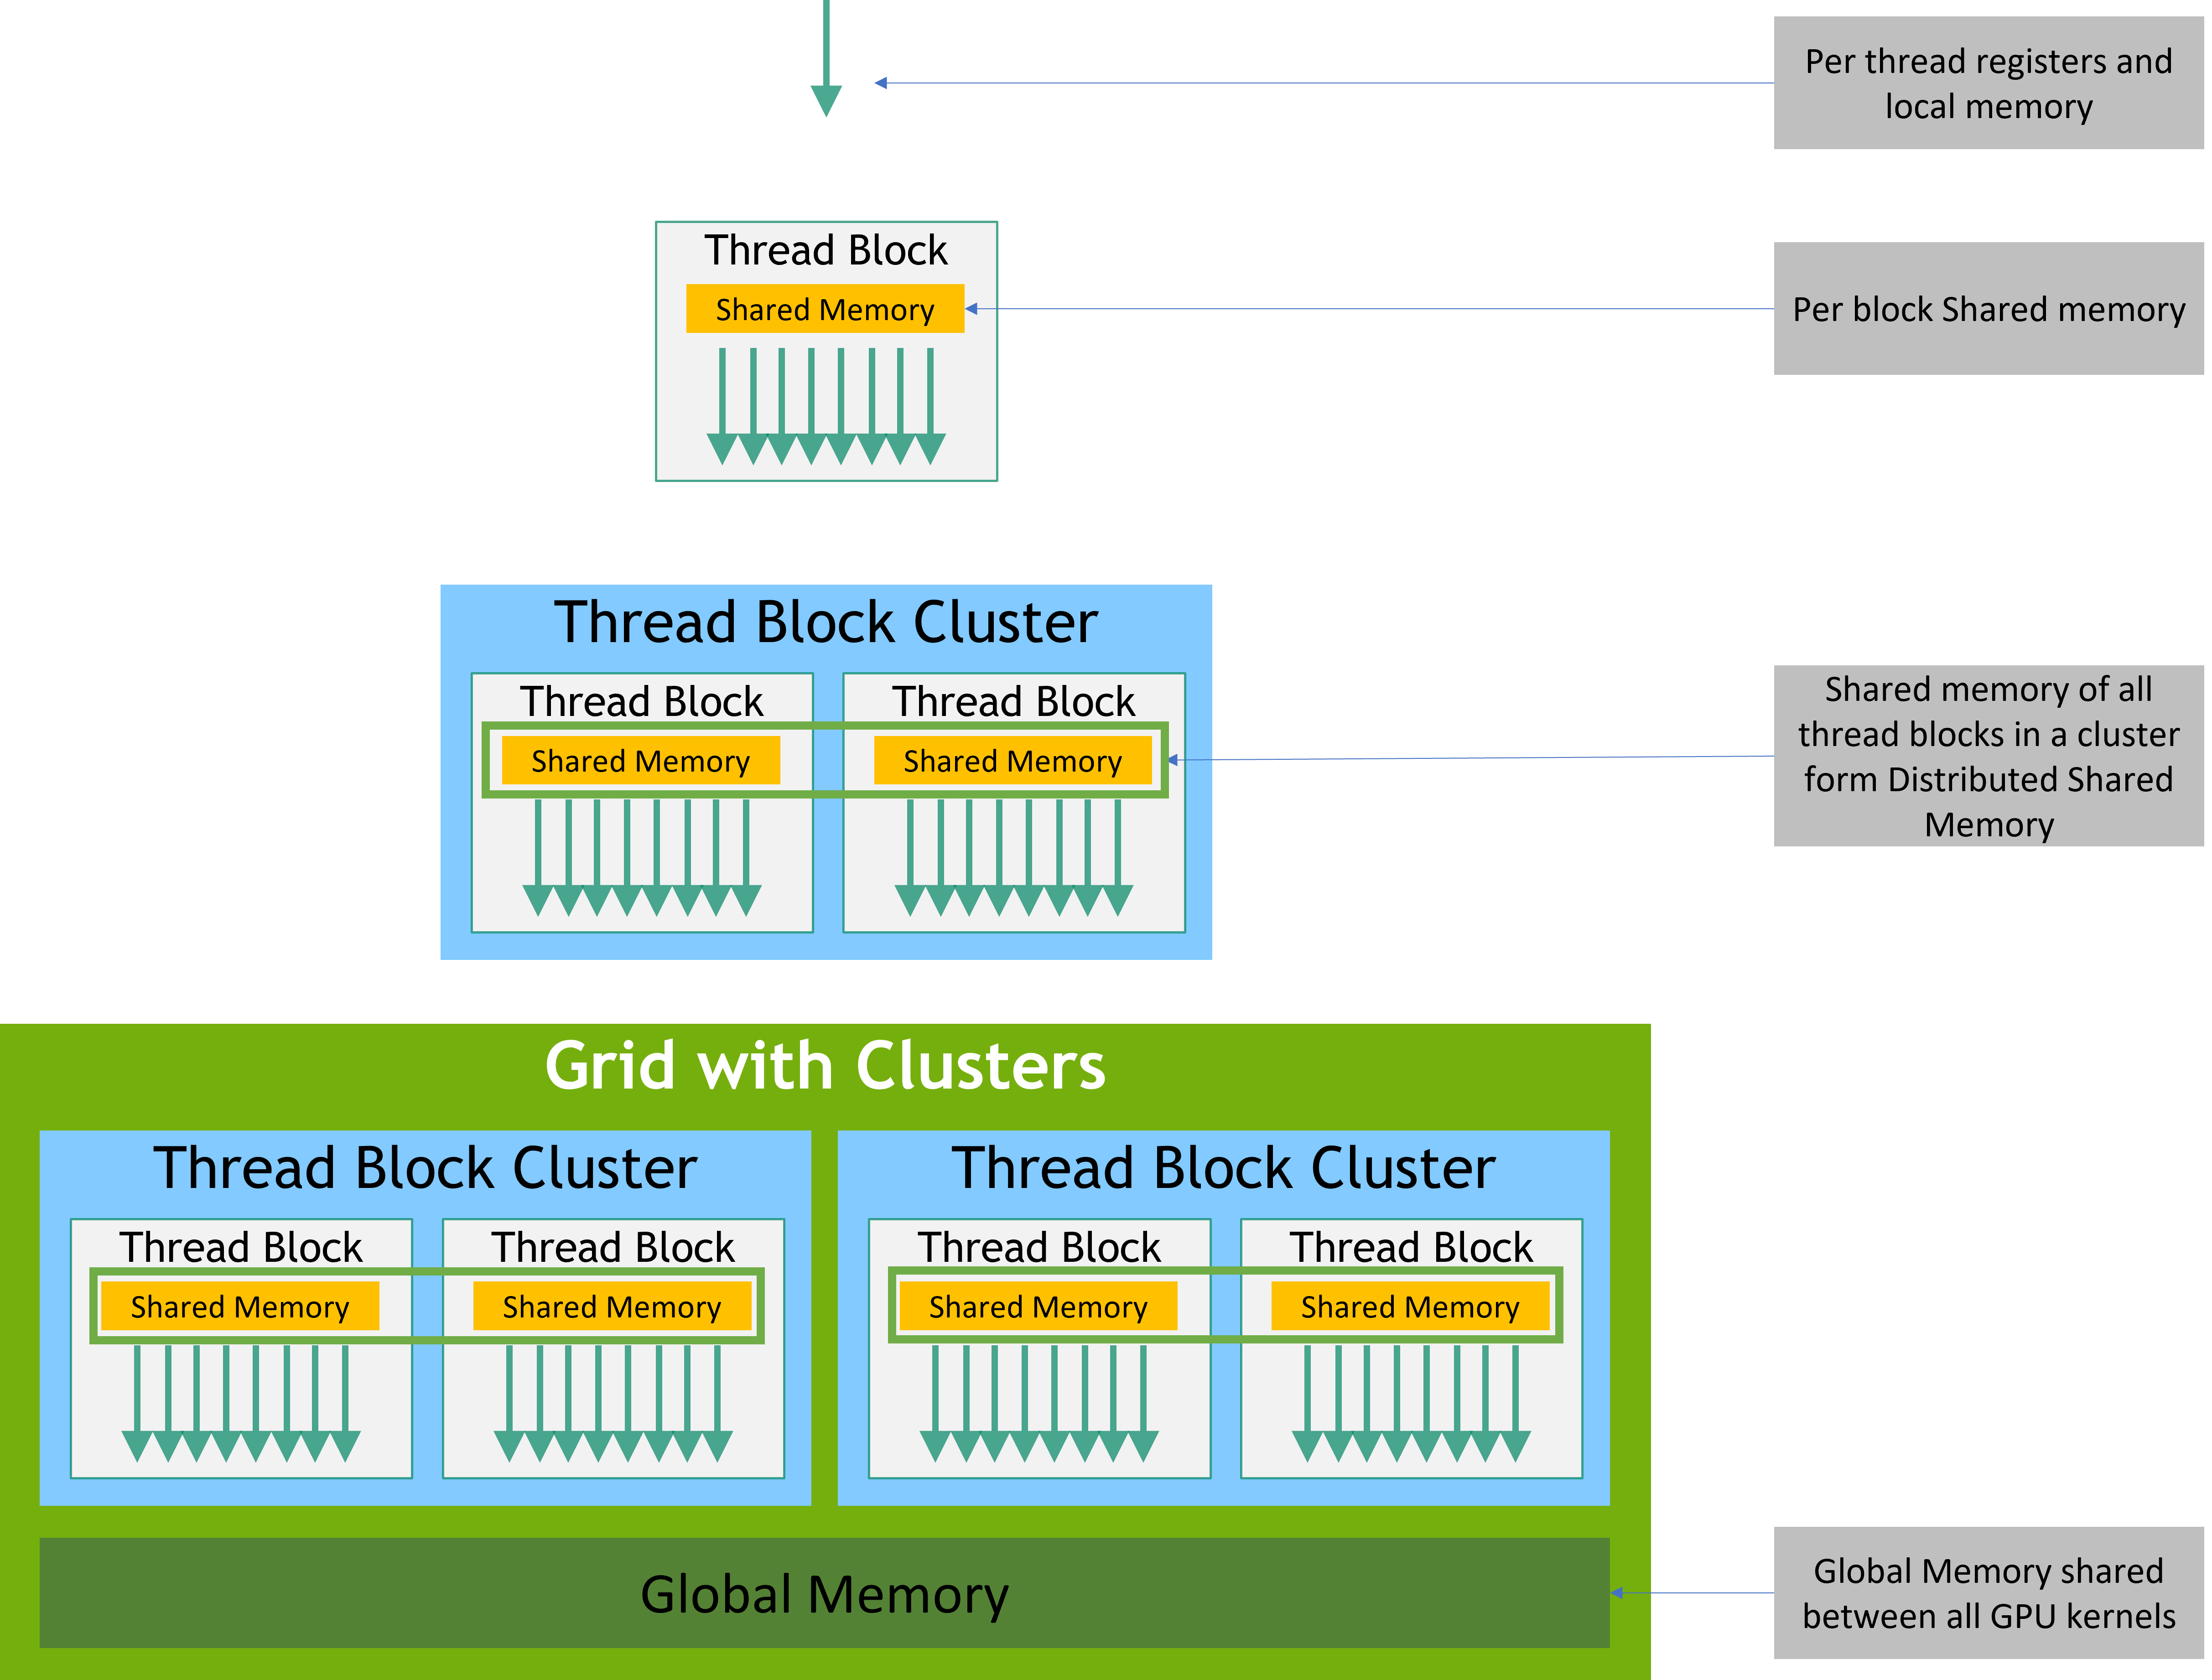
Source: NVIDIA CUDA Programming Guide
6.1 Memory space summary¶
| Space | Typical visibility and lifetime | What to verify |
|---|---|---|
| Registers | Per-thread values while active | Allocation, dependencies, spills, occupancy |
| Local memory | Per-thread addressable storage | Device-memory traffic despite the word “local” |
| Shared memory | Block lifetime; cluster access where supported | Capacity, banks, initialization, synchronization |
| Global memory | Accessible by device threads with valid pointers | Coalescing, caches, bandwidth, ordering |
| Constant memory | Read-only device symbols/cache path | Access pattern and per-symbol/device limits |
| L1/L2 caches | Hardware-managed cached data | Target organization and measured hit/miss behavior |
Latency and bandwidth are properties of the target and access pattern. Registers have finite throughput and dependent-instruction latency; there is no universal “zero cycles, unlimited bandwidth” storage level. Separate a capacity specification from a measured latency or achieved bandwidth.
6.2 Register and Local Memory¶
__global__ void kernel() {
    int x = 5;        // register (fast, private per thread)
    float arr[10];    // may spill to local memory if too large
    // local memory = per-thread DRAM — very slow, avoid large on-stack arrays
}
Register spilling: If a thread uses too many registers, the compiler stores the overflow in slow local memory (off-chip DRAM). Detect with nvcc --ptxas-options=-v.
6.3 Shared Memory¶
Shared memory is explicitly managed on-chip storage shared by a block. It can reduce repeated global-memory traffic, but its benefit depends on reuse, bank behavior, synchronization, and occupancy.
__global__ void use_shared(float* in, float* out, int N) {
    __shared__ float tile[256];   // allocated at compile time

    int tid = threadIdx.x;
    int gid = blockIdx.x * blockDim.x + threadIdx.x;

    // Load from global into shared
    tile[tid] = (gid < N) ? in[gid] : 0.0f;
    __syncthreads();   // ← CRITICAL: all threads must finish loading

    // Now process from shared (fast)
    tile[tid] = tile[tid] * 2.0f;
    __syncthreads();

    // Write back to global
    if (gid < N) out[gid] = tile[tid];
}
Dynamic shared memory (size determined at launch):
__global__ void kernel(float* data) {
    extern __shared__ float smem[];   // size determined at launch
    smem[threadIdx.x] = data[...];
    // ...
}

// Launch: third argument = shared memory bytes
kernel<<<grid, block, 256 * sizeof(float)>>>(data);
Request more than 48 KB per block:
// Required for > 48 KB shared memory (Ampere+)
cudaFuncSetAttribute(my_kernel,
    cudaFuncAttributeMaxDynamicSharedMemorySize,
    96 * 1024);  // 96 KB

my_kernel<<<grid, block, 96 * 1024>>>(args);
6.4 Global Memory Allocation¶
float *d_data;
cudaMalloc(&d_data, N * sizeof(float));   // allocate
cudaFree(d_data);                          // free

// Transfers
cudaMemcpy(d_data, h_data, bytes, cudaMemcpyHostToDevice);   // H→D
cudaMemcpy(h_data, d_data, bytes, cudaMemcpyDeviceToHost);   // D→H
cudaMemcpy(d_dst, d_src,   bytes, cudaMemcpyDeviceToDevice); // D→D

// Zero-initialize
cudaMemset(d_data, 0, bytes);
Pinned (page-locked) host memory — faster H↔D transfers:
float *h_data;
cudaMallocHost(&h_data, bytes);   // allocate pinned host memory
// OR: cudaHostAlloc(&h_data, bytes, cudaHostAllocDefault);

// Use exactly like regular memory
// Pinned memory enables eligible asynchronous transfer paths; measure throughput.

cudaFreeHost(h_data);
Unified Memory — single pointer accessible from both CPU and GPU:
float *data;
cudaMallocManaged(&data, bytes);   // managed allocation

// Use on CPU
for (int i = 0; i < N; i++) data[i] = 1.0f;

// Use on GPU — CUDA runtime migrates pages automatically
kernel<<<grid, block>>>(data, N);
cudaDeviceSynchronize();

// Use on CPU again — migrates back
printf("%f\n", data[0]);

cudaFree(data);
6.5 Constant Memory¶
For read-only data shared by all threads — cached with broadcast (one read serves all 32 threads in a warp):
__constant__ float weights[1024];

__global__ void apply_weights(float* data, int N) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < N) data[i] *= weights[i % 1024];   // all threads read same value: broadcast
}

// Host-side: copy to constant memory
cudaMemcpyToSymbol(weights, h_weights, 1024 * sizeof(float));
7. Warp Execution and SIMT¶
7.1 SIMT — Single Instruction, Multiple Threads¶
A warp is 32 threads. The SM issues one instruction to all 32 lanes simultaneously. This is hardware-level SIMD, but each thread has its own registers and can follow its own control flow.
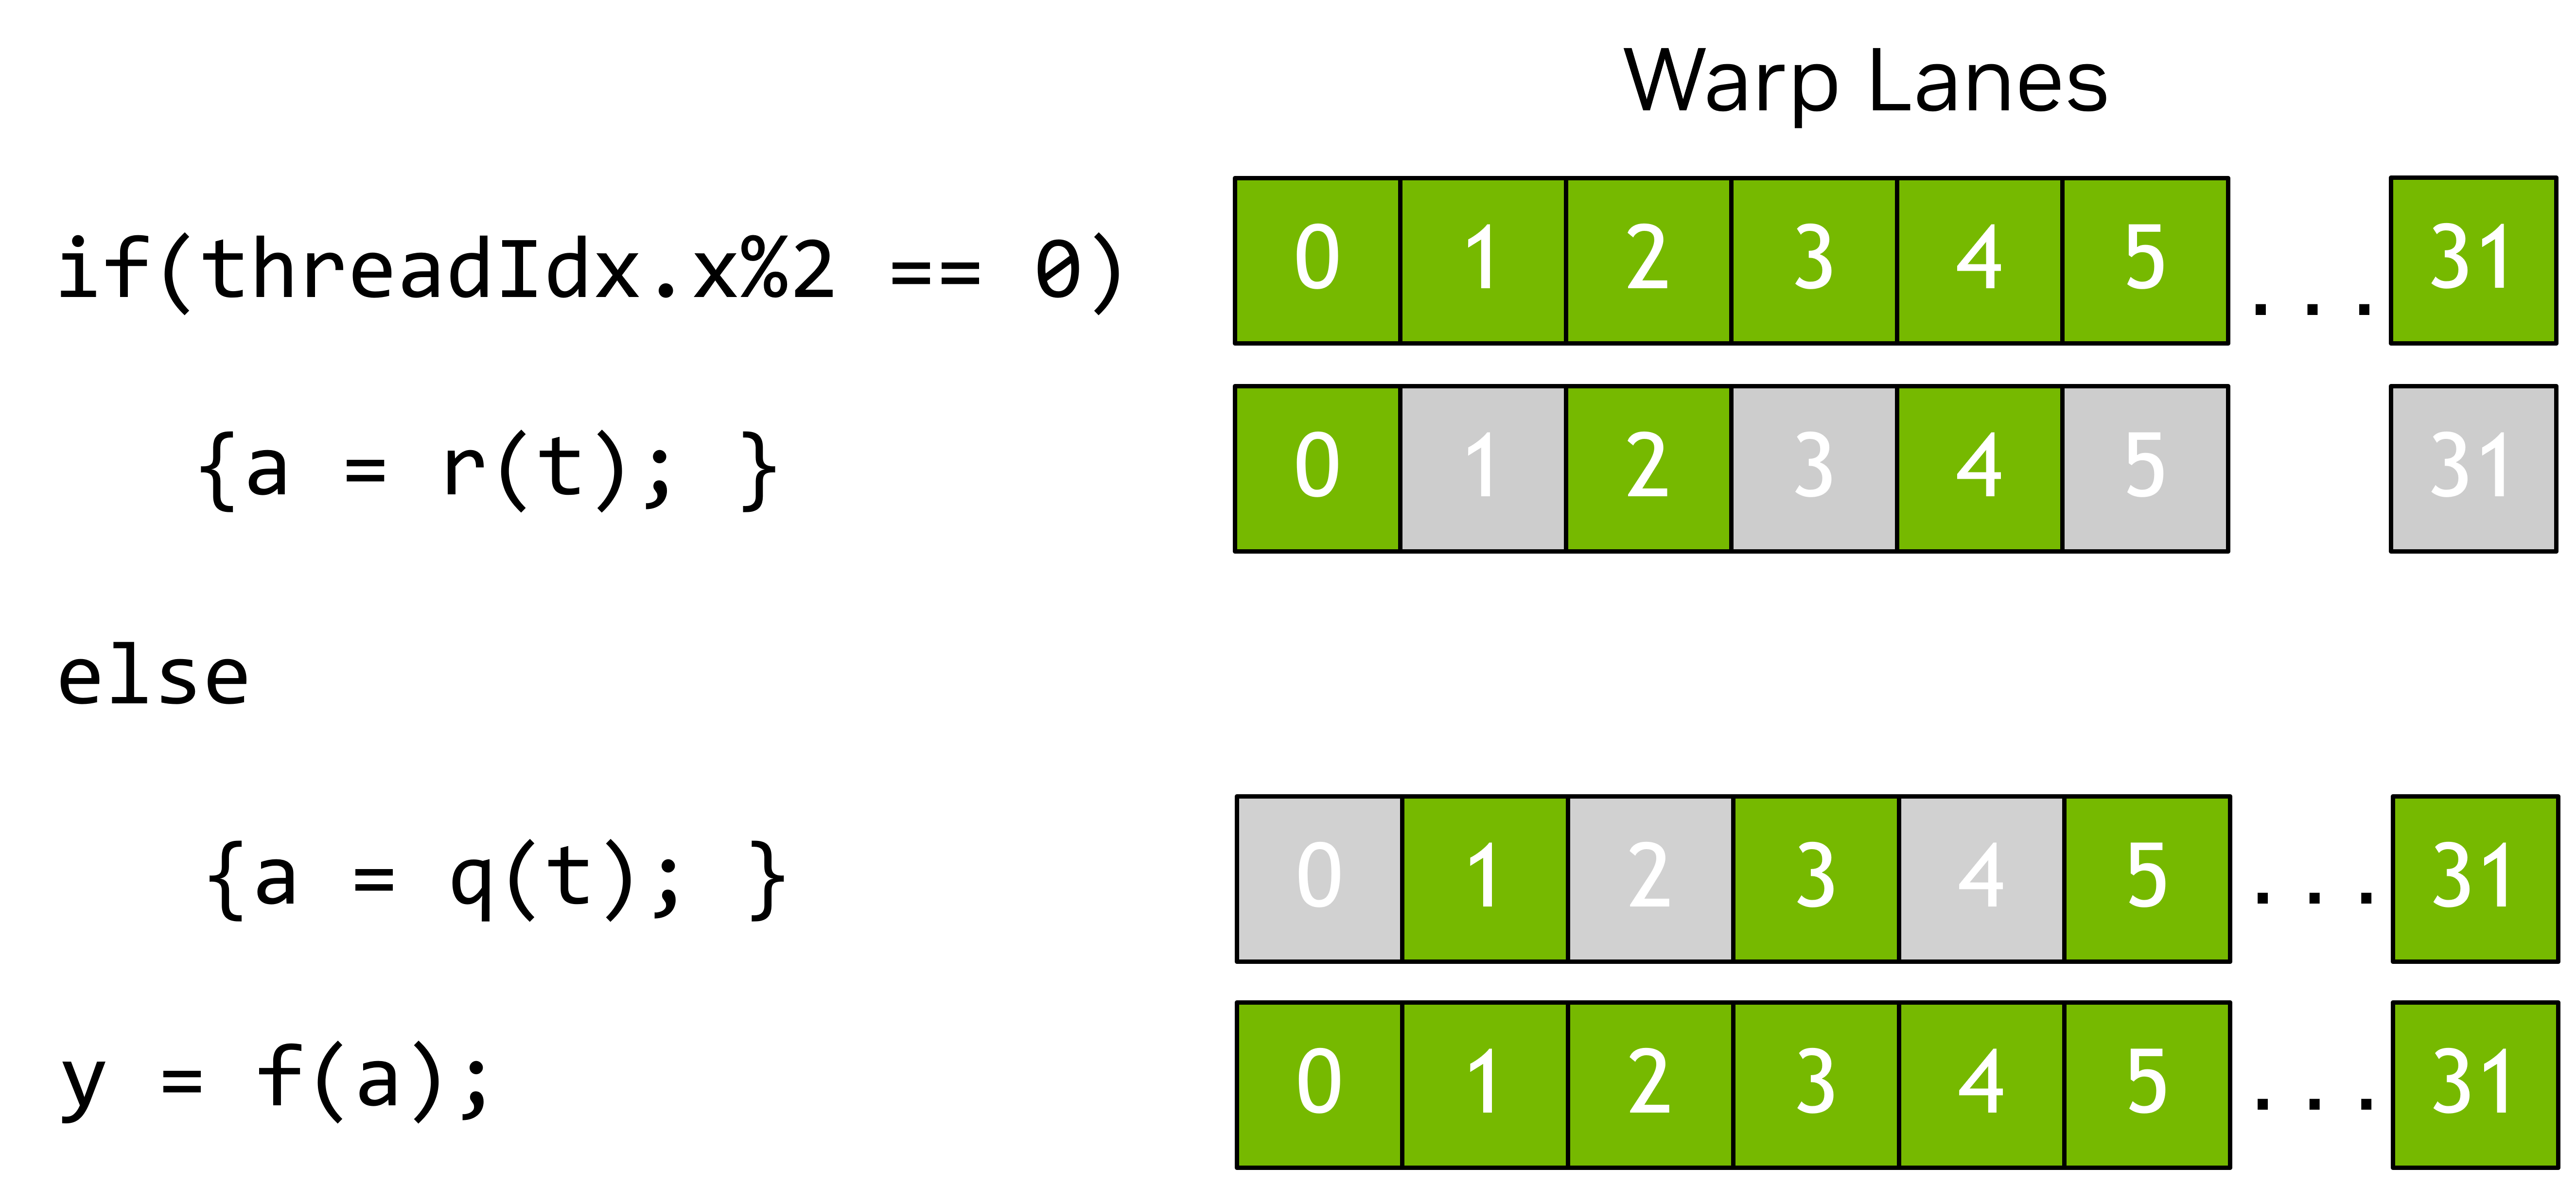
Active vs inactive lanes in a warp. Inactive lanes (diverged threads) are masked off — they consume time but produce no output. Source: NVIDIA
7.2 Warp divergence and predication¶
Threads in a warp can take different control-flow paths. The hardware/compiler must preserve each thread's result while scheduling those paths. Divergence cost depends on path length, active-lane patterns, memory behavior, and reconvergence; it is not automatically a twofold slowdown.
A compiler may implement this with a select, predicated instructions, or a branch. A ternary expression does not guarantee a specific instruction. CPU compilers can also produce conditional moves or vector blends, so branchless lowering is not exclusive to GPUs. Inspect generated code and profile before rewriting clear control flow.
Arithmetic selection such as mask*a + (1-mask)*b is not generally equivalent to choosing a or b: 0*NaN remains NaN, infinities and signed zero can change results, and both branches may perform expensive work or invalid accesses. Preserve the numerical and memory contract.
Exercise: if only three lanes need an expensive fallback, should every lane compute both paths? Answer: not necessarily. Compare validated implementations; the useful work and memory accesses matter more than removing the word if.
7.3 Occupancy — Hiding Latency¶
The GPU hides memory latency by switching to other resident warps while one warp waits. More resident warps = more latency hiding = higher throughput.
SM capacity: 2048 resident threads (H100) = 64 warps
If block size = 256 → 8 warps/block → 8 blocks resident per SM
If block size = 32  → 1 warp/block  → 64 blocks resident per SM (but tiny blocks waste overhead)
If block size = 1024 → 32 warps/block → 2 blocks = 64 warps = 100% occupancy
Occupancy is limited by: 1. Registers per thread — more registers = fewer threads fit 2. Shared memory per block — more shared mem = fewer blocks fit 3. Max threads per SM — hard limit
Find an occupancy-based starting configuration:
int block_size, min_grid;
cudaOccupancyMaxPotentialBlockSize(&min_grid, &block_size, my_kernel, 0, 0);
printf("Optimal block size: %d\n", block_size);

// Query actual occupancy
int active_blocks;
cudaOccupancyMaxActiveBlocksPerMultiprocessor(&active_blocks, my_kernel, block_size, 0);
float occupancy = (active_blocks * block_size) / (float)props.maxThreadsPerMultiProcessor;
printf("Occupancy: %.1f%%\n", occupancy * 100);
8. Memory Coalescing¶
For the common compute-capability 6.0+ model, count the 32-byte segments touched by a warp's memory instruction. A full warp reading 32 aligned, consecutive FP32 values needs four segments; shifting the start by one float can require five. Scattered addresses can touch up to 32 segments. Transaction counts do not translate directly into a fixed slowdown because caches, reuse, and other bottlenecks matter. See the CUDA coalescing guide.
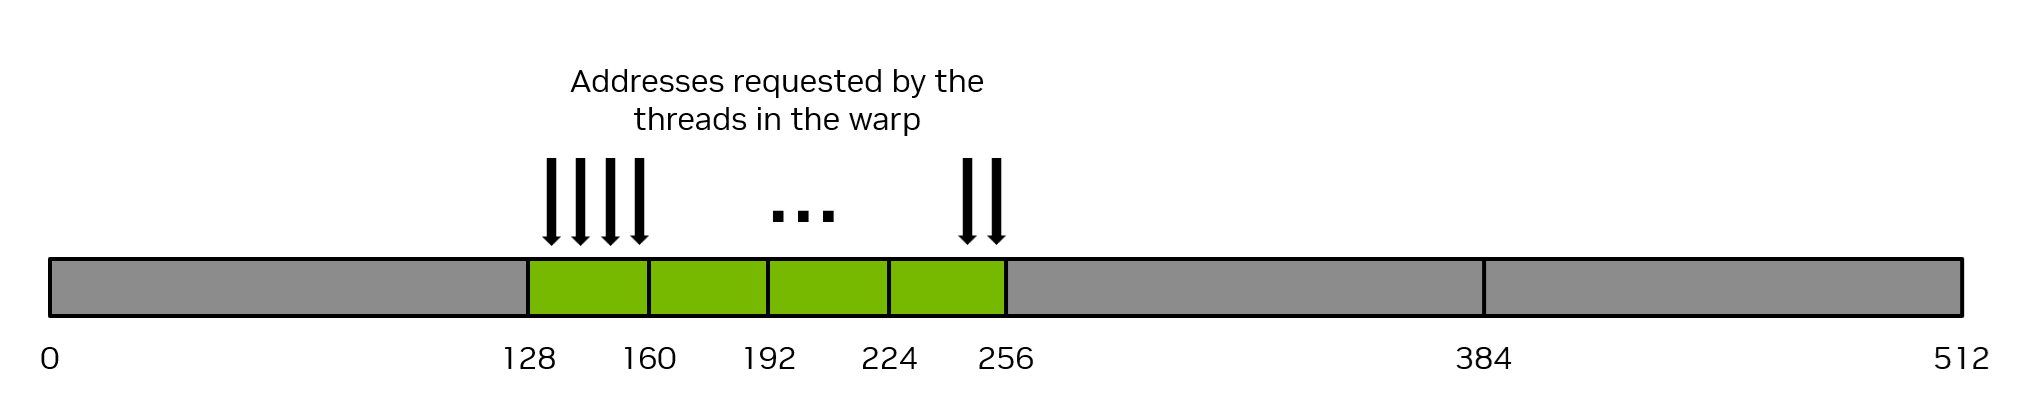
Consecutive FP32 values occupy 128 useful bytes; the modern segment model counts four aligned 32-byte transactions. Interpret older diagrams using the target's documented transaction granularity.
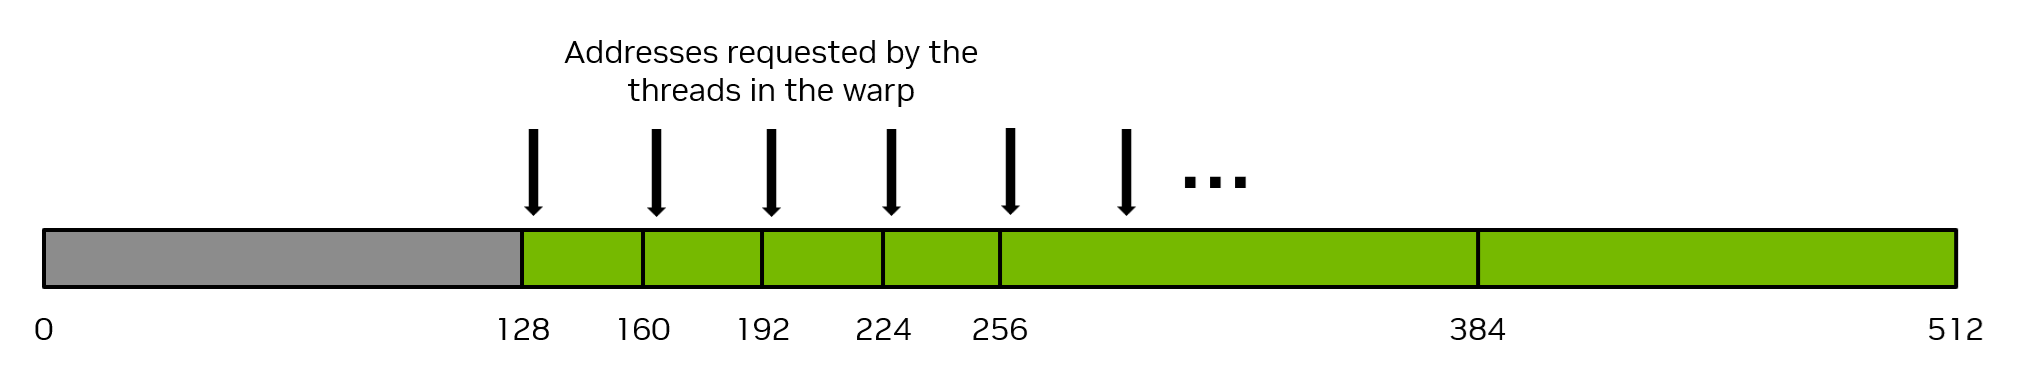
Scattered accesses → multiple transactions, wasted bandwidth. Source: NVIDIA
Coalesced (good):
// Thread i accesses a[i] — consecutive, perfectly coalesced
__global__ void coalesced(float* a, float* b, float* c, int N) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < N) c[i] = a[i] + b[i];
}
Strided (bad):
// Contract: stride > 0, N >= 0; inputs have N elements and c has ceil(N/stride).
// Thread i accesses a[i * stride].
__global__ void strided(float* a, float* b, float* c, int stride, int N) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i <= (N - 1) / stride && N > 0)
        c[i] = a[i * stride] + b[i * stride];
}
// Aligned stride=4: 32 lanes request 128 bytes across 16 segments (512 bytes).
// That is 25% requested-byte utilization for this load, before cache reuse.
Fix strided access with transpose or SoA layout (see AoS vs SoA in SIMD guide).
9. Shared Memory and Bank Conflicts¶
Shared memory is divided into 32 banks, each 4 bytes wide. Bank k holds addresses k, k+32, k+64, etc.
If multiple threads in a warp access different addresses in the same bank, that's a bank conflict — serialized. If all threads access the same address in one bank, it's a broadcast — no conflict.
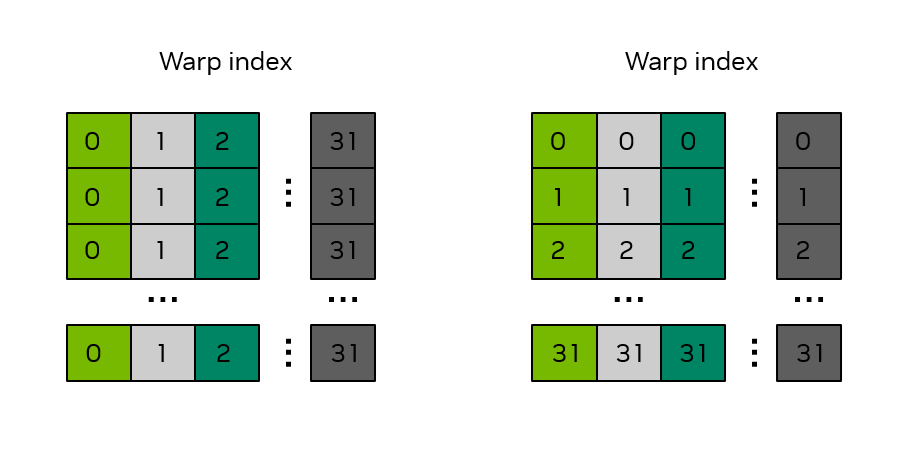
Source: NVIDIA CUDA Programming Guide
// No conflict: thread i accesses bank i
__shared__ float smem[32];
float val = smem[threadIdx.x];          // OK: thread 0→bank 0, thread 1→bank 1, ...

// 2-way bank conflict: thread 0 and 16 both access bank 0
float val = smem[threadIdx.x * 2];     // BAD: stride 2 → 2-way conflict

// Fix: pad the array
__shared__ float smem[32 + 1];         // +1 pad shifts all addresses
float val = smem[threadIdx.x * 2];     // Now stride-2 is conflict-free

// 32-way conflict (broadcast): all threads read the same element
float val = smem[0];                   // OK — hardware broadcasts, no conflict
Matrix transpose (classic bank conflict example):
#define TILE 32

__global__ void transpose(float* out, const float* in, int width, int height) {
    __shared__ float tile[TILE][TILE + 1];   // +1 padding avoids conflicts

    int x = blockIdx.x * TILE + threadIdx.x;
    int y = blockIdx.y * TILE + threadIdx.y;

    if (x < width && y < height)
        tile[threadIdx.y][threadIdx.x] = in[y * width + x];   // coalesced read

    __syncthreads();

    x = blockIdx.y * TILE + threadIdx.x;
    y = blockIdx.x * TILE + threadIdx.y;

    if (x < height && y < width)
        out[y * height + x] = tile[threadIdx.x][threadIdx.y]; // coalesced write
}
9.1 Shared Memory Is Actually Flat¶
The GPU sees shared memory as one long line of addresses. When you declare __shared__ float tile[32][32], the GPU doesn't know about "rows" and "columns" — it's just 1,024 consecutive floats.
What the GPU sees (flat):
  smem[0]  smem[1]  smem[2]  ...  smem[31]  smem[32]  smem[33]  ...  smem[1023]
  ├──────── Row 0 (32 elements) ──────────┤ ├──────── Row 1 ──────────────────┤

What YOU see (2D grid):
  Row 0:  smem[0]   smem[1]   smem[2]  ...  smem[31]
  Row 1:  smem[32]  smem[33]  smem[34] ...  smem[63]
  Row 2:  smem[64]  smem[65]  smem[66] ...  smem[95]

Index formula:  flat_index = row × width + col
Banks are assigned by the flat index: bank = flat_index % 32.
9.2 Why Column Access Causes Bank Conflicts¶
When a warp of 32 threads reads one row (consecutive elements), each thread hits a different bank — no conflict:
Row access: thread i reads smem[row][i] = smem[row × 32 + i]

  Thread 0 → index 0  → Bank 0
  Thread 1 → index 1  → Bank 1
  Thread 2 → index 2  → Bank 2
  ...
  Thread 31 → index 31 → Bank 31

  All 32 banks hit once → no conflict ✓
But when threads read one column (same col, different rows), every thread hits the same bank:
Column access: thread i reads smem[i][col] = smem[i × 32 + col]

  Width = 32 (no padding):
  Thread 0 → index 0×32 + 0 = 0   → Bank 0 % 32 = 0
  Thread 1 → index 1×32 + 0 = 32  → Bank 32 % 32 = 0  ← SAME BANK!
  Thread 2 → index 2×32 + 0 = 64  → Bank 64 % 32 = 0  ← SAME BANK!
  Thread 3 → index 3×32 + 0 = 96  → Bank 96 % 32 = 0  ← SAME BANK!

  → 32-way bank conflict! Serialized to 32 sequential accesses.
  → up to 32 distinct-address bank requests serialize in this simplified model; kernel slowdown requires measurement.
9.3 The +1 Padding Fix — Visually¶
Adding one padding element per row changes the width from 32 to 33. Now column accesses hit different banks:
__shared__ float tile[32][32 + 1];   // width = 33

Column access with padding:
  Thread 0 → index 0×33 + 0 = 0   → Bank 0 % 32 = 0
  Thread 1 → index 1×33 + 0 = 33  → Bank 33 % 32 = 1   ← different!
  Thread 2 → index 2×33 + 0 = 66  → Bank 66 % 32 = 2   ← different!
  Thread 3 → index 3×33 + 0 = 99  → Bank 99 % 32 = 3   ← different!

  → All 32 threads hit different banks → no conflict ✓
The complete picture:
Without padding (width = 32):              With padding (width = 33):

Col 0 access:                              Col 0 access:
  Row 0: index  0 → Bank 0                  Row 0: index  0 → Bank 0
  Row 1: index 32 → Bank 0  ← conflict!     Row 1: index 33 → Bank 1  ✓
  Row 2: index 64 → Bank 0  ← conflict!     Row 2: index 66 → Bank 2  ✓
  Row 3: index 96 → Bank 0  ← conflict!     Row 3: index 99 → Bank 3  ✓

Col 5 access:                              Col 5 access:
  Row 0: index  5 → Bank 5                  Row 0: index  5 → Bank 5
  Row 1: index 37 → Bank 5  ← conflict!     Row 1: index 38 → Bank 6  ✓
  Row 2: index 69 → Bank 5  ← conflict!     Row 2: index 71 → Bank 7  ✓
  Row 3: index101 → Bank 5  ← conflict!     Row 3: index104 → Bank 8  ✓
Cost of padding: one extra FP32 element per row adds 128 bytes for a 32-row tile. It removes the illustrated 32-way conflict, but kernel speedup also depends on other instructions and memory traffic. Check the access width and bank mapping before applying this layout to another dtype or instruction.
9.4 Bank Conflict Patterns Quick Reference¶
| Access pattern | Bank conflict | Fix |
|---|---|---|
smem[threadIdx.x] (stride 1) |
None | Already perfect |
smem[threadIdx.x * 2] (stride 2) |
2-way | Pad or remap |
smem[threadIdx.x * 32] (column, width 32) |
32-way (worst!) | +1 padding |
smem[same_index] (broadcast) |
None | Hardware broadcasts |
smem[row][threadIdx.x] (row read) |
None | Natural row-major |
smem[threadIdx.x][col] (column read) |
32-way | Declare as [N][N+1] |
9.5 Row Access vs Column Access — CUDA Examples¶
Row access (safe, no conflicts):
// Every thread reads a different column in the SAME row → stride 1 → no conflict
__shared__ float tile[32][32];

int col = threadIdx.x;   // each thread picks a different column
float val = tile[0][col]; // row 0, varying column

// Thread 0 → tile[0][0]  = flat index 0  → Bank 0
// Thread 1 → tile[0][1]  = flat index 1  → Bank 1
// Thread 2 → tile[0][2]  = flat index 2  → Bank 2
// ...
// Thread 31 → tile[0][31] = flat index 31 → Bank 31
// ✓ All 32 banks hit → no conflict → full speed
Row access is like kids taking lockers in order: locker 0, 1, 2, 3 → smooth flow. No padding needed.
Column access (conflicts, needs fix):
// Every thread reads a different ROW in the SAME column → stride 32 → 32-way conflict!
__shared__ float tile[32][32];

int row = threadIdx.x;    // each thread picks a different row
float val = tile[row][0]; // varying row, column 0

// Thread 0 → tile[0][0]  = flat index 0   → Bank 0
// Thread 1 → tile[1][0]  = flat index 32  → Bank 0  ← SAME!
// Thread 2 → tile[2][0]  = flat index 64  → Bank 0  ← SAME!
// Thread 3 → tile[3][0]  = flat index 96  → Bank 0  ← SAME!
// ✗ All threads hit Bank 0 → 32-way distinct-address bank conflict in this simplified model
Column access is like all kids jumping to the same locker pattern: locker 0, 32, 64 → traffic jam.
Column access with +1 padding (fixed):
// Same column access, but width = 33 instead of 32
__shared__ float tile[32][33];   // ← +1 padding

int row = threadIdx.x;
float val = tile[row][0];

// Thread 0 → flat index 0×33 + 0 = 0   → Bank 0
// Thread 1 → flat index 1×33 + 0 = 33  → Bank 1  ← different!
// Thread 2 → flat index 2×33 + 0 = 66  → Bank 2  ← different!
// Thread 3 → flat index 3×33 + 0 = 99  → Bank 3  ← different!
// ✓ All different banks → no conflict → full speed
// Cost: 1 extra float per row (128 bytes total) — trivial
9.6 Complete Example — Matrix Transpose with Bank Conflict Fix¶
Matrix transpose is the classic use case: you read rows (safe) but write columns (conflict). The +1 padding makes both directions conflict-free.
#define TILE 32

__global__ void transpose_naive(float* out, const float* in, int W, int H) {
    // BAD: column write causes 32-way bank conflict
    __shared__ float tile[TILE][TILE];

    int x = blockIdx.x * TILE + threadIdx.x;
    int y = blockIdx.y * TILE + threadIdx.y;

    if (x < W && y < H)
        tile[threadIdx.y][threadIdx.x] = in[y * W + x];    // row write ✓

    __syncthreads();

    x = blockIdx.y * TILE + threadIdx.x;
    y = blockIdx.x * TILE + threadIdx.y;

    if (x < H && y < W)
        out[y * H + x] = tile[threadIdx.x][threadIdx.y];   // column read ✗ CONFLICT!
}

__global__ void transpose_padded(float* out, const float* in, int W, int H) {
    // GOOD: +1 padding eliminates column bank conflicts
    __shared__ float tile[TILE][TILE + 1];   // ← the fix

    int x = blockIdx.x * TILE + threadIdx.x;
    int y = blockIdx.y * TILE + threadIdx.y;

    if (x < W && y < H)
        tile[threadIdx.y][threadIdx.x] = in[y * W + x];    // row write ✓

    __syncthreads();

    x = blockIdx.y * TILE + threadIdx.x;
    y = blockIdx.x * TILE + threadIdx.y;

    if (x < H && y < W)
        out[y * H + x] = tile[threadIdx.x][threadIdx.y];   // column read ✓ (padded)
}

// No device benchmark is supplied here. Validate square and rectangular tails,
// then report device, shape, launch, warmup, event timing, and byte convention.
9.7 Advanced — Shared Memory Swizzling¶
Padding changes storage size and alignment. Some optimized kernels use a carefully selected swizzle to map their access pattern to banks while preserving required layouts. An arbitrary XOR is not a universal conflict-free transformation; derive it for the actual instruction, element size, and lane mapping.
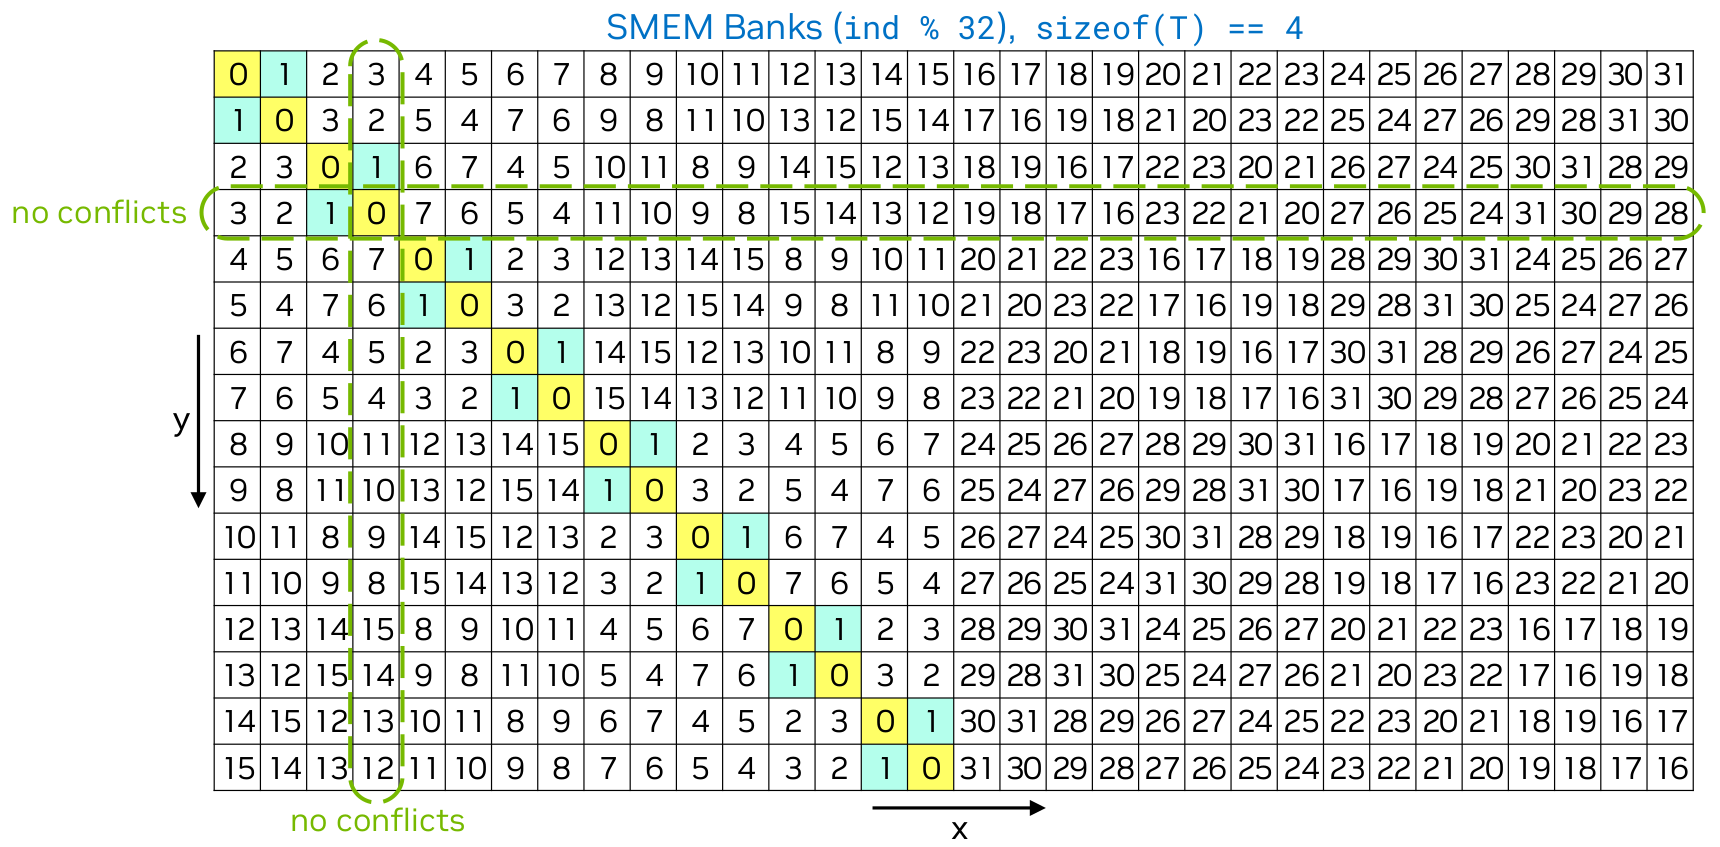
Swizzling remaps addresses so that column accesses automatically land on different banks, without padding. Source: Lei Mao's blog.
// Swizzled access: XOR row bits into column index
// Instead of:  tile[row][col]
// Use:         tile[row][col ^ (row % num_banks)]

// Example for 32 banks:
int swizzled_col = col ^ (row & 31);
float val = tile[row][swizzled_col];

// Row 0, col 0: 0 ^ 0 = 0  → Bank 0
// Row 1, col 0: 0 ^ 1 = 1  → Bank 1
// Row 2, col 0: 0 ^ 2 = 2  → Bank 2
// Row 3, col 0: 0 ^ 3 = 3  → Bank 3
// No padding needed, no wasted memory, no alignment issues.
Swizzling is used internally by CUTLASS and cuBLAS. For your own kernels, +1 padding is simpler and nearly as effective.
9.8 When You Need Padding vs When You Don't¶
| Situation | Padding needed? | Why |
|---|---|---|
| Reading rows from shared memory | No | Threads access consecutive addresses → all different banks |
| Writing rows to shared memory | No | Same reason — stride 1 is always safe |
| Reading columns from shared memory | Yes | Threads access stride-32 → all same bank |
| Writing columns to shared memory | Yes | Same reason |
| Matrix transpose (read row, write col) | Yes | The write side has column access |
| Tiled matmul (A tile read by row) | No | Row access is natural |
| Tiled matmul (B tile read by column) | Yes | B is often accessed column-wise in the K loop |
| Already using swizzling | No | Swizzling handles it without padding |
Rule of thumb: if any access pattern in your kernel has threads reading the same column (or any stride that's a multiple of 32), add +1 to the last dimension. Cost: negligible. Benefit: up to 32× speedup for that access.
10. Synchronization¶
Three levels of synchronization, each with different scope and cost:
| Function | Scope | Cost | When to use |
|---|---|---|---|
__syncthreads() |
Thread block (all threads) | High | After shared memory writes, before reads |
__syncwarp() |
Warp (32 threads) | Low | Fast coordination within one warp |
__syncwarp(mask) |
Sub-warp (selected lanes) | Very low | Divergent execution paths |
10.1 __syncthreads() — Block-Wide Barrier¶
All threads in a thread block must reach this point before any thread continues. The most common synchronization primitive in CUDA.
__global__ void block_sync_example(float* input, float* output) {
    __shared__ float shared[256];
    int tid = threadIdx.x;
    int idx = blockIdx.x * blockDim.x + tid;

    // Step 1: every thread loads one element into shared memory
    shared[tid] = input[idx];

    // Step 2: BARRIER — wait for ALL threads to finish writing
    __syncthreads();

    // Step 3: now safe — all 256 values are in shared memory
    // Thread 0 can read shared[255] because thread 255 has finished writing
    if (tid == 0) {
        float sum = 0.0f;
        for (int i = 0; i < blockDim.x; i++)
            sum += shared[i];
        output[blockIdx.x] = sum;
    }
}
Without __syncthreads(): thread 0 might read shared[200] before thread 200 has written it → garbage result. The barrier guarantees all writes complete before any reads.
Barrier rule: a conditional block barrier is valid only when its condition is uniform across the block. A divergent subset must not execute a barrier that the other participating threads skip:
// WRONG: some threads may not reach __syncthreads()
if (threadIdx.x < 16) {
    smem[threadIdx.x] = data[threadIdx.x];
    __syncthreads();   // ← UB: threads 16–31 never reach this → DEADLOCK
}

// CORRECT: barrier outside the conditional
smem[threadIdx.x] = (threadIdx.x < 16) ? data[threadIdx.x] : 0;
__syncthreads();       // all threads hit this — safe
10.2 __syncwarp() — Warp Barrier¶
Synchronizes only the 32 threads in one warp. Faster than __syncthreads() because no cross-warp coordination needed.
__global__ void warp_sync_example(int* data) {
    int tid = threadIdx.x;
    int lane = tid % 32;         // lane within warp

    int val = data[tid];

    // Warp-level computation
    val += 1;

    // Sync only this warp's 32 threads
    __syncwarp();

    // Now all 32 lanes in this warp have updated val
    // Safe to use warp shuffle operations
    int neighbor = __shfl_xor_sync(0xFFFFFFFF, val, 1);  // exchange with neighbor
    data[tid] = val + neighbor;
}
When to use: warp shuffle operations (__shfl_sync), warp vote (__ballot_sync), or any warp-cooperative algorithm where you need to ensure all lanes have finished a prior step.
10.3 __syncwarp(mask) — Partial Warp Sync¶
Synchronizes only the lanes specified by the bitmask. Avoids forcing inactive lanes to wait.
__global__ void masked_sync_example(int* data) {
    int tid = threadIdx.x;
    int lane = tid % 32;

    int val = data[tid];

    bool active = (lane % 2 == 0);  // only even lanes participate

    if (active) {
        val += 10;  // only even lanes modify
    }

    // Mask: 0xAAAAAAAA = 10101010... (bits set for even lanes: 0, 2, 4, ...)
    // Wait: 0x55555555 would be odd lanes
    unsigned even_mask = 0x55555555;  // lanes 0, 2, 4, 6, ...
    __syncwarp(even_mask);

    if (active) {
        data[tid] = val;  // only even lanes write — guaranteed they all finished
    }
}
When to use: branch-divergent algorithms where only some lanes are active (graph traversal, sparse matrix operations, conditional AI inference paths). Avoids the overhead of syncing lanes that aren't participating.
10.4 Synchronization in Tiled Matmul (Real Pattern)¶
The most common sync pattern in AI kernels — load tile, sync, compute, sync, repeat:
__global__ void matmul_tiled(float* A, float* B, float* C, int N) {
    __shared__ float As[TILE][TILE];
    __shared__ float Bs[TILE][TILE];
    float sum = 0.0f;

    for (int t = 0; t < N / TILE; t++) {
        // Phase 1: ALL threads cooperatively load one tile
        As[threadIdx.y][threadIdx.x] = A[...];
        Bs[threadIdx.y][threadIdx.x] = B[...];

        __syncthreads();   // ← BARRIER 1: tile fully loaded before compute

        // Phase 2: ALL threads compute using the loaded tile
        for (int k = 0; k < TILE; k++)
            sum += As[threadIdx.y][k] * Bs[k][threadIdx.x];

        __syncthreads();   // ← BARRIER 2: compute done before loading next tile
    }
    // Two barriers per tile iteration — load/compute/load/compute...
    C[...] = sum;
}
Why two barriers per iteration: - Barrier 1: ensures tile is fully loaded before any thread reads from it - Barrier 2: ensures all threads finished reading before the tile is overwritten with the next chunk
Missing either barrier → race condition → wrong results (often intermittent, hard to debug).
10.5 Warp Shuffle — Pass Data Between Threads Without Shared Memory¶
Warp shuffles are the most powerful warp-level primitive. They let threads exchange register values directly — no shared memory, no barrier, no memory traffic. Just register-to-register communication across lanes.
The four shuffle operations:
// 1. Direct lane read: "give me value from thread src_lane"
float val = __shfl_sync(0xFFFFFFFF, my_val, src_lane);
//   Every thread gets the value from thread src_lane
//   Example: __shfl_sync(mask, my_val, 0) → all threads get thread 0's value

// 2. Shift down: thread i gets value from thread i+delta
float val = __shfl_down_sync(0xFFFFFFFF, my_val, delta);
//   Lane 0 gets Lane delta's value, Lane 1 gets Lane (1+delta)'s value, ...
//   Lanes at the end (i+delta >= 32) get their own value (no wrap)

// 3. Shift up: thread i gets value from thread i-delta
float val = __shfl_up_sync(0xFFFFFFFF, my_val, delta);

// 4. XOR exchange: thread i gets value from thread (i XOR lane_mask)
float val = __shfl_xor_sync(0xFFFFFFFF, my_val, lane_mask);
//   Example: mask=1 → exchange with neighbor (0↔1, 2↔3, ...)
//   Example: mask=16 → exchange with lane 16 apart (0↔16, 1↔17, ...)
Why shuffles beat shared memory:
| Shared memory | Warp shuffle | |
|---|---|---|
| Cost | Loads/stores and possible conflicts; measure on the target | Cross-lane instructions and dependencies; measure on the target |
| Synchronization | Match barrier scope to producer/consumer scope | All named lanes must participate in the corresponding _sync operation |
| Storage | Finite shared-memory allocation | Finite registers; more live values can reduce occupancy or spill |
| Bank conflicts | Possible | Impossible |
| Scope | Entire block | Within one warp (32 threads) |
10.6 Warp Reduction — The Classic Pattern¶
Sum all 32 values in a warp using shuffle-down in 5 steps. Precondition: all 32 lanes execute every shuffle with the full mask. For a partial data tile, launch a complete warp and supply zero for out-of-range elements; do not return early before the collective. An arbitrary sparse participation mask requires a different reduction algorithm.
__device__ float warp_reduce_sum(float val) {
    for (int offset = 16; offset > 0; offset >>= 1)
        val += __shfl_down_sync(0xFFFFFFFF, val, offset);
    return val;   // lane 0 has the sum of all 32 lanes
}
Step-by-step (simplified to 8 lanes for clarity):
Initial:    lane: 0  1  2  3  4  5  6  7
            val:  a  b  c  d  e  f  g  h

Step 1 (offset=4):  each lane += value from lane+4
            lane 0: a+e    lane 1: b+f    lane 2: c+g    lane 3: d+h
            lane 4: e      lane 5: f      lane 6: g      lane 7: h

Step 2 (offset=2):  each lane += value from lane+2
            lane 0: a+e+c+g    lane 1: b+f+d+h
            lane 2: c+g        lane 3: d+h

Step 3 (offset=1):  each lane += value from lane+1
            lane 0: a+b+c+d+e+f+g+h  ← SUM OF ALL VALUES
            lane 1: b+f+d+h

Result: lane 0 = sum(all 8 values) in just 3 steps (log₂(8))
For 32 lanes: 5 steps (log₂(32))
No shared memory used. No __syncthreads(). Just 5 __shfl_down_sync calls.
10.7 Block Reduction — Warp + Shared Memory Hybrid¶
For this example, launch exactly 256 threads in a one-dimensional block, and have every thread call the function. Combine eight warp results through shared memory. Only thread 0's return value is the final block sum.
__device__ float block_reduce_sum(float val) {
    // Step 1: reduce within each warp (shuffle, no shared mem)
    val = warp_reduce_sum(val);

    // Step 2: collect warp results into shared memory
    __shared__ float warp_results[8];   // one slot per warp (256 threads / 32 = 8 warps)
    int lane = threadIdx.x % 32;
    int warp = threadIdx.x / 32;

    if (lane == 0)
        warp_results[warp] = val;       // lane 0 of each warp writes its sum
    __syncthreads();

    // Step 3: first warp reduces the 8 warp results
    if (warp == 0) {
        val = (lane < 8) ? warp_results[lane] : 0.0f;
        val = warp_reduce_sum(val);     // 8 values → 1 final sum
    }

    return val;  // thread 0 has the block sum
}
This teaching pattern needs one block barrier plus synchronized warp exchanges. It is not a universal optimum. For general shapes and thread counts, prefer a tested library collective such as CUB and compare generated code and runtime on the target.
10.8 Hardware Warp Reductions (Ampere+ / SM 8.0+)¶
On compute capability 8.0+, the GPU has dedicated reduction hardware:
// Integer reductions; these intrinsics do not accept float values.
int   isum = __reduce_add_sync(0xFFFFFFFF, ival);
int   imax = __reduce_max_sync(0xFFFFFFFF, ival);

// Bitwise
unsigned and_result = __reduce_and_sync(0xFFFFFFFF, uval);
unsigned or_result  = __reduce_or_sync(0xFFFFFFFF, uval);
Use the supported signed/unsigned integer overloads and obey the participation mask. Floating-point reductions need a suitable shuffle/library implementation. These intrinsics do not order memory accesses; see NVIDIA's warp-reduction specification.
10.9 Warp Vote — Collective Boolean Operations¶
// Do ALL active lanes satisfy the predicate?
bool all_done = __all_sync(0xFFFFFFFF, my_flag);

// Does ANY lane satisfy the predicate?
bool any_ready = __any_sync(0xFFFFFFFF, data_available);

// Get a bitmask of which lanes satisfy the predicate
unsigned mask = __ballot_sync(0xFFFFFFFF, val > threshold);
// mask bit i = 1 if lane i's (val > threshold) is true
// Example: mask = 0x0000FF00 → lanes 8–15 passed, others didn't

// Count how many lanes passed
int count = __popc(mask);   // population count (count set bits)
Use cases in AI:
- Attention masking: __ballot_sync to find which tokens are valid
- Early exit: __all_sync(mask, converged) — stop iterating when all lanes converge
- Sparse operations: __popc(__ballot_sync(...)) — count non-zero elements in warp
10.10 When to Use What¶
| Need | Best primitive | Why |
|---|---|---|
| Supported integer sum/max/min | Corresponding __reduce_*_sync (SM 8.0+) |
Check type and participation contract |
| Floating-point sum or another target | CUB or a validated shuffle reduction | Match target, types, and active lanes |
| Exchange with neighbor | __shfl_xor_sync(mask, val, 1) |
Butterfly pattern |
| Broadcast one value to all lanes | __shfl_sync(mask, val, src_lane) |
Read from specific lane |
| Prefix sum (scan) | __shfl_up_sync loop |
Build partial sums |
| Count true conditions | __ballot_sync + __popc |
Bitmask + popcount |
| Check all/any convergence | __all_sync / __any_sync |
Collective boolean |
| Block-wide reduction | Warp shuffle + 1 shared mem step | Hybrid (section 10.7) |
| Cross-block reduction | Library reduction, staged kernels, or appropriate atomics/cooperative launch | Choose supported synchronization and numerical order |
10.11 Atomic Operations¶
// Atomic add (global or shared memory)
atomicAdd(&counter, 1);
atomicAdd(&shared_sum, val);

// Other atomics
atomicSub(&counter, 1);
atomicMax(&max_val, val);
atomicMin(&min_val, val);
atomicCAS(&lock, 0, 1);      // compare-and-swap: if *lock==0, set to 1, return old

// FP16 atomics (SM 7.0+)
atomicAdd((__half*)ptr, (__half)val);
Performance tip: never do atomicAdd from every thread. First reduce within warp (shuffle), then reduce within block (shared mem), then ONE thread per block does the atomic:
// BAD: 10,000 threads all doing atomicAdd → massive contention
atomicAdd(out, val);

// GOOD: reduce first, one atomic per block
float block_sum = block_reduce_sum(val);
if (threadIdx.x == 0)
    atomicAdd(out, block_sum);   // only 1 atomic per block, not 256
11. Streams and Asynchronous Execution¶
Streams allow overlapping GPU computation with host execution and with data transfers.
cudaStream_t stream1, stream2;
cudaStreamCreate(&stream1);
cudaStreamCreate(&stream2);

// Overlapping compute and copy
cudaMemcpyAsync(d_a, h_a, bytes, cudaMemcpyHostToDevice, stream1);
kernel<<<grid, block, 0, stream1>>>(d_a, d_out, N);
cudaMemcpyAsync(h_out, d_out, bytes, cudaMemcpyDeviceToHost, stream1);

// Different work on stream2, runs concurrently with stream1
other_kernel<<<grid, block, 0, stream2>>>(d_b, d_out2, N);

// Synchronize
cudaStreamSynchronize(stream1);   // wait for stream1
cudaStreamSynchronize(stream2);   // wait for stream2

cudaStreamDestroy(stream1);
cudaStreamDestroy(stream2);
Stream timeline (overlapping copy + compute):
Stream 1:  [copy H→D] [kernel] [copy D→H]
Stream 2:             [copy H→D] [kernel] [copy D→H]
           ─────────────────────────────────────────► time
Events for precise timing and cross-stream sync:
cudaEvent_t start, stop;
cudaEventCreate(&start);
cudaEventCreate(&stop);

cudaEventRecord(start, stream1);
kernel<<<grid, block, 0, stream1>>>(args);
cudaEventRecord(stop, stream1);

cudaEventSynchronize(stop);
float ms;
cudaEventElapsedTime(&ms, start, stop);
printf("Kernel time: %.3f ms\n", ms);

cudaEventDestroy(start);
cudaEventDestroy(stop);
12. How It All Connects — The GPU Performance Stack¶
Sections 12–19 cover many GPU features. Before diving in, here's how they all fit together as four layers of GPU performance, from top (CPU-side) to bottom (hardware limits):
Layer 1: CPU ↔ GPU Scheduling
  ┌─────────────────────────────────────────────────────┐
  │  CUDA Graphs (§13)         — reduce CPU submission overhead      │
  │  Streams (§11)             — overlap copy + compute          │
  │  Automatic Scalability (§19) — same code, any GPU size       │
  └─────────────────────────────────────────────────────┘
                              │
Layer 2: Kernel Memory Efficiency
  ┌─────────────────────────────────────────────────────┐
  │  Tiled Matmul (§15)        — load once, reuse TILE× times   │
  │  Reduction (§14)           — collapse N values in log(N) steps│
  │  Shared Memory (§9)        — on-chip staging, bank conflicts │
  │  Coalesced Access (§8)     — minimize DRAM transactions      │
  └─────────────────────────────────────────────────────┘
                              │
Layer 3: Intra-Warp Efficiency
  ┌─────────────────────────────────────────────────────┐
  │  Warp Shuffle (§10.5)      — register-to-register, no memory│
  │  Warp Reduction (§10.6-8)  — 5-step sum, no shared memory   │
  │  Warp Vote (§10.9)         — ballot/all/any for branching    │
  │  Branchless/Predication (§7.2) — avoid warp divergence       │
  └─────────────────────────────────────────────────────┘
                              │
Layer 4: Hardware Accelerators
  ┌─────────────────────────────────────────────────────┐
  │  Tensor Cores (§16)        — 16×16 matrix in one instruction │
  │  Thread Block Clusters (§4.3) — distributed shared memory   │
  │  Cooperative Groups (§18)  — flexible sync at any granularity│
  │  Dynamic Parallelism (§17) — GPU launches GPU (niche)        │
  └─────────────────────────────────────────────────────┘
                              │
                              ▼
              ┌──────────────────────────────┐
              │  Roofline Limit (§20)         │
              │  Performance = min(           │
              │    compute peak,             │
              │    memory bandwidth × AI     │
              │  )                            │
              │  You can't exceed this —     │
              │  only get closer to it.      │
              └──────────────────────────────┘
How to use this stack when debugging performance:
Is your kernel slow?
│
├── Step 1: Is CPU the bottleneck?
│   └── Yes → CUDA Graphs (§13). Can reduce repeated submission overhead; measure the actual launch path.
│        Graphs don't make GPU faster — they make CPU overhead disappear.
│
├── Step 2: Is it memory-bound?
│   └── Yes → Tiling (§15). Load once from DRAM, reuse 16–128× from shared memory.
│        Every DRAM read you eliminate = direct speedup.
│        Check coalescing (§8): thread N must access address N.
│
├── Step 3: Is synchronization the bottleneck?
│   └── Yes → Warp shuffles (§10.5) replace __syncthreads + shared memory.
│        Shuffle = 1 cycle, register-only. Shared mem = 5 cycles + sync.
│        Block reduction → warp shuffle first, ONE shared mem step (§10.7).
│
├── Step 4: Is warp divergence hurting?
│   └── Yes → Branchless arithmetic (§7.2). Ternary → compiler emits SEL.
│        Sort input data so adjacent threads take same path.
│
├── Step 5: Is compute underutilized?
│   └── Yes → Tensor Cores (§16). Choose a supported matrix instruction and verify dtype/layout/shape.
│        WMMA fragments must be 16-aligned. Use cuBLAS for automatic TC.
│
└── Step 6: Still slow?
    └── Roofline (§20). Calculate arithmetic intensity.
         If AI < ridge point → bandwidth-limited → quantize, fuse, batch.
         If AI > ridge point → compute-limited → more Tensor Cores, wider tiles.
         You cannot exceed the roofline — only approach it.
Use the measured bottleneck: some kernels are bandwidth-bound, some compute-bound, and some dominated by launch, dependency, or synchronization costs. Candidate optimizations include: - Tiling and data reuse (Layer 2) give the biggest speedups - Warp shuffles (Layer 3) save shared memory bandwidth - Matrix instructions can reduce compute cost, but overall benefit depends on the remaining bottlenecks - CUDA Graphs (Layer 1) help when many small kernels dominate
13. CUDA Graphs¶
For workloads that repeat the same sequence of kernels and transfers, CUDA graphs reduce repeated CPU submission overhead by capturing and replaying the entire execution graph.
// Step 1: capture a sequence of operations
cudaGraph_t graph;
cudaStreamBeginCapture(stream, cudaStreamCaptureModeGlobal);

kernel_a<<<grid, block, 0, stream>>>(d_a, N);
kernel_b<<<grid, block, 0, stream>>>(d_a, d_b, N);
cudaMemcpyAsync(h_out, d_b, bytes, cudaMemcpyDeviceToHost, stream);

cudaStreamEndCapture(stream, &graph);

// Step 2: instantiate (compile the graph)
cudaGraphExec_t graph_exec;
cudaGraphInstantiate(&graph_exec, graph, nullptr, nullptr, 0);

// Step 3: launch repeatedly (minimal CPU overhead)
for (int iter = 0; iter < 1000; iter++) {
    cudaGraphLaunch(graph_exec, stream);
    cudaStreamSynchronize(stream);
}

// Cleanup
cudaGraphExecDestroy(graph_exec);
cudaGraphDestroy(graph);
When to use graphs: - Same kernel sequence repeated many times (training loops, inference batches) - Many small kernels where launch overhead dominates - Measure capture/instantiation, first replay, steady replay, and device completion separately; graph launch still has overhead.
14. Parallel Reduction — Complete Example¶
Reduction is the canonical shared memory + sync pattern. Modern GPUs require explicit synchronization: volatile is not a substitute for a warp collective. See NVIDIA’s independent-thread-scheduling guidance. This teaching snippet uses the error-checking conventions from §5.4 when incorporated into a complete program; test ragged input sizes and numerical tolerance against a CPU reference.
// Parallel sum reduction — each block reduces its chunk to one value
__global__ void reduce_sum(const float* in, float* partial, int N) {
    extern __shared__ float smem[];

    int tid = threadIdx.x;
    int gid = blockIdx.x * blockDim.x * 2 + threadIdx.x;  // × 2: each thread loads 2

    // Load two elements per thread
    float val = 0.0f;
    if (gid < N)         val += in[gid];
    if (gid + blockDim.x < N) val += in[gid + blockDim.x];
    smem[tid] = val;
    __syncthreads();

    // Tree reduction in shared memory
    for (int stride = blockDim.x / 2; stride > 32; stride >>= 1) {
        if (tid < stride)
            smem[tid] += smem[tid + stride];
        __syncthreads();
    }

    // The preceding block barrier makes the final 64 partials visible.
    // Contract: blockDim.x is a power of two and at least 64 (host uses 256).
    if (tid < 32) {
        float sum = smem[tid] + smem[tid + 32];
        // All 32 lanes participate; the intrinsic provides the warp exchange.
        for (int offset = 16; offset > 0; offset >>= 1)
            sum += __shfl_down_sync(0xffffffffu, sum, offset);
        if (tid == 0) partial[blockIdx.x] = sum;
    }
}

// Host: launch reduce_sum, then sum the partial results
float gpu_sum(const float* d_in, int N) {
    if (N <= 0) return 0.0f;
    int block = 256;
    int grid  = (N + block * 2 - 1) / (block * 2);

    float *d_partial;
    cudaMalloc(&d_partial, grid * sizeof(float));

    reduce_sum<<<grid, block, block * sizeof(float)>>>(d_in, d_partial, N);

    // Recursively reduce if needed, or just copy partial to host and sum there
    std::vector<float> h_partial(grid);
    cudaMemcpy(h_partial.data(), d_partial, grid * sizeof(float), cudaMemcpyDeviceToHost);
    cudaFree(d_partial);

    return std::accumulate(h_partial.begin(), h_partial.end(), 0.0f);
}
15. Tiled Matrix Multiply — Shared Memory Optimization¶
#define TILE_SIZE 16

__global__ void tiled_matmul(
    const float* A, const float* B, float* C,
    int M, int N, int K)  // C[M×N] = A[M×K] * B[K×N]
{
    __shared__ float As[TILE_SIZE][TILE_SIZE];
    __shared__ float Bs[TILE_SIZE][TILE_SIZE];

    int row = blockIdx.y * TILE_SIZE + threadIdx.y;
    int col = blockIdx.x * TILE_SIZE + threadIdx.x;

    float sum = 0.0f;

    // Iterate over tiles of K
    for (int t = 0; t < (K + TILE_SIZE - 1) / TILE_SIZE; t++) {
        // Cooperative load: each thread loads one element
        int a_col = t * TILE_SIZE + threadIdx.x;
        int b_row = t * TILE_SIZE + threadIdx.y;

        As[threadIdx.y][threadIdx.x] = (row < M && a_col < K) ? A[row * K + a_col] : 0.0f;
        Bs[threadIdx.y][threadIdx.x] = (b_row < K && col < N) ? B[b_row * N + col]  : 0.0f;
        __syncthreads();

        // Compute partial dot product for this tile
        for (int k = 0; k < TILE_SIZE; k++)
            sum += As[threadIdx.y][k] * Bs[k][threadIdx.x];
        __syncthreads();
    }

    if (row < M && col < N)
        C[row * N + col] = sum;
}
Why tiling works:
Naive matmul:
  Each C[i][j] loads K elements from A (row i) and K from B (col j)
  Total global loads: M*N*2K = O(MNK) → memory bound for large K

Tiled matmul with TILE=16:
  Each 16×16 block of C cooperatively loads one 16×16 tile from A and B
  Each load reused 16 times within the tile
  Memory traffic reduced by ~TILE_SIZE = 16×
  Compute:memory ratio increased → compute bound (much faster)
16. Tensor Cores¶
Tensor Cores provide matrix arithmetic introduced with Volta. WMMA is a collective programming interface; one API call is not necessarily one hardware instruction or one cycle.
#include <mma.h>
using namespace nvcuda::wmma;

// Tensor Core: 16×16×16 GEMM (FP16 input, FP32 accumulator)
__global__ void tensor_core_matmul(
    const half* A, const half* B, float* C, int M, int N, int K)
{
    // Teaching contract: one full warp per block, M/N/K multiples of 16.
    // A and B are row-major, with valid padded storage/alignment for WMMA.
    fragment<matrix_a, 16, 16, 16, half, row_major> a_frag;
    fragment<matrix_b, 16, 16, 16, half, row_major> b_frag;
    fragment<accumulator, 16, 16, 16, float>         c_frag;

    fill_fragment(c_frag, 0.0f);

    for (int k = 0; k < K; k += 16) {
        load_matrix_sync(a_frag, A + blockIdx.y * 16 * K + k, K);
        load_matrix_sync(b_frag, B + k * N + blockIdx.x * 16, N);
        mma_sync(c_frag, a_frag, b_frag, c_frag);   // D = A*B + C
    }

    store_matrix_sync(C + blockIdx.y * 16 * N + blockIdx.x * 16, c_frag, N, mem_row_major);
}
Read performance specifications with their scope attached. A whole-device advertised FLOP/s value is not a per-SM rate. Record precision, accumulation type, dense versus structured-sparse mode, device variant, and power configuration. Then compare measured useful operations and end-to-end latency for the actual shape.
cuBLAS and cuDNN select algorithms using supported types, layouts, alignment, sizes, and configuration. Multiples of 16 alone do not guarantee Tensor Core use or a faster end-to-end result. Check the selected algorithm and profiler counters rather than assuming dispatch from the matrix dimensions.
17. Dynamic Parallelism¶
Dynamic parallelism lets GPU code launch additional grids. It is an advanced option for runtime-generated work, with launch overhead and no guarantee that parent and child grids execute concurrently.
Current API boundary: CDP2 is the default from CUDA 12.0 and is required for compute capability 9.0+. Device-side cudaDeviceSynchronize() is unavailable in that model. Follow NVIDIA's current dynamic-parallelism documentation for parent/child visibility and tail-launch continuation. Host-side completion checks remain distinct.
// Conceptual CDP2 launch sketch; not executed in the CPU-only course checks.
// data points to N allocated floats in global memory; N >= 0.
__global__ void child_kernel(float* data, int N) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;
    if (i < N) data[i] *= 2.0f;
}

__global__ void parent_kernel(float* data, int N) {
    // Exactly one thread launches the child grid for this example.
    if (blockIdx.x == 0 && threadIdx.x == 0 && N > 0)
        child_kernel<<<1 + (N - 1) / 256, 256>>>(data, N);
    // Do not read child results back in this parent body.
}
Build a complete host harness using the selected toolkit's device-runtime/linking instructions. Validate target support, launch/completion errors, and results. Compare with one direct host-launched child kernel before adding nested launches: for this simple transform, dynamic parallelism adds machinery without removing useful work.
18. Cooperative Groups¶
Cooperative groups let you express sync and reduction at any granularity — warp, block, multi-block, or grid.
#include <cooperative_groups.h>
namespace cg = cooperative_groups;

__global__ void flexible_reduction(float* data, float* out, int N) {
    auto block = cg::this_thread_block();  // all threads in this block
    auto warp  = cg::tiled_partition<32>(block);  // this warp
    auto tile  = cg::tiled_partition<4>(block);   // group of 4 threads

    float val = data[block.thread_rank()];

    // Warp reduce
    for (int i = warp.size() / 2; i > 0; i >>= 1)
        val += warp.shfl_down(val, i);

    // Write warp result
    if (warp.thread_rank() == 0)
        atomicAdd(out, val);
}

// Grid-wide sync (requires cudaLaunchCooperativeKernel)
__global__ void grid_sync_kernel(float* data) {
    auto grid = cg::this_grid();
    // ... do phase 1 ...
    grid.sync();   // all threads in grid synchronize
    // ... do phase 2 ...
}
19. Automatic Scalability¶
CUDA programs scale automatically across different GPU sizes. The same grid runs on a GPU with 4 SMs or 144 SMs — the runtime schedules blocks to available SMs.
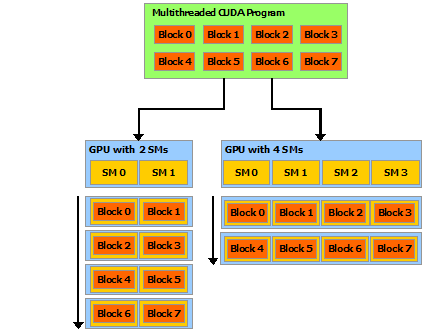
The same program scales automatically: 2 SMs run 2 blocks at a time, 4 SMs run 4 blocks at a time. Source: NVIDIA
This is why you write for maximum parallelism and let the hardware decide — don't hardcode grid sizes to a specific GPU.
20. Performance Optimization Checklist¶
Step 1 — Profile First¶
# NVIDIA Nsight Systems (timeline, CPU/GPU overlap)
nsys profile --stats=true ./my_program

# NVIDIA Nsight Compute (kernel-level metrics)
ncu --set full ./my_program
Step 2 — Roofline Analysis¶
Roofline gives a compute/bandwidth upper bound. Launch overhead, dependency chains, synchronization, or insufficient parallelism can keep a kernel below both roofs.
attainable FLOP/s <= min(sustained compute roof, sustained bytes/s × FLOP/byte)
ridge FLOP/byte = compute FLOP/s / memory bytes/s

Illustrative device (not a measured product result):
  compute = 100 TFLOP/s, bandwidth = 1 TB/s
  ridge   = (100 × 10^12) / (1 × 10^12) = 100 FLOP/byte
Match precision, dense/sparse execution, and memory level on both sides. Dividing TFLOP/s by GB/s requires a factor of 1000; do not compare a dense FP16 kernel to a sparse FP8 marketing roof. Then use measured bytes and elapsed time to test the predicted limit.
Step 3 — Common Optimizations¶
| Issue | Symptom | Fix |
|---|---|---|
| Low occupancy | Kernel uses many registers | Reduce register pressure; use __launch_bounds__ |
| Uncoalesced access | High DRAM traffic in Nsight | Restructure to SoA; transpose before processing |
| Bank conflicts | Shared mem replay in Nsight | Pad shared arrays (+1 column) |
| Warp divergence | Low warp execution efficiency | Branchless arithmetic; sort inputs first |
| Too many atomics | High contention | Use per-warp/per-block local accumulators first |
| Launch overhead | Kernel takes < 50 µs but lots of launches | Use CUDA Graphs |
| CPU-GPU idle time | GPU idle in timeline | Async transfers + streams |
Step 4 — Launch Bounds¶
The second argument guides register allocation; it does not guarantee four blocks actually reside on an SM. Other resources and launch constraints still apply.
// Tell the compiler max threads per block and min blocks per SM
// Helps compiler tune register allocation for better occupancy
__launch_bounds__(256, 4)   // max threads; register-allocation target for 4 resident blocks
__global__ void my_kernel(float* data, int N) { ... }
21. Compute Capability Quick Reference¶
| Arch | CC | GPU Examples | FP16 TC | BF16 | FP8 | TMA | Clusters |
|---|---|---|---|---|---|---|---|
| Volta | 7.0 | V100 | ✓ | — | — | — | — |
| Turing | 7.5 | RTX 2080, T4 | ✓ | — | — | — | — |
| Ampere | 8.0 | A100 | ✓ | ✓ | — | — | — |
| Ampere | 8.6 | RTX 3090, A10 | ✓ | ✓ | — | — | — |
| Hopper | 9.0 | H100 | ✓ | ✓ | ✓ | ✓ | ✓ |
| Blackwell | 10.x | B100, B200 | ✓ | ✓ | ✓ | ✓ | ✓ |
| Newer products | Query exact SKU | Consult vendor support table | Verify | Verify | Verify | Verify | Verify |
Resource limits: query the exact device and consult its tuning guide. For the H100 case, per-SM shared capacity, maximum per-block allocation, and the combined L1/shared pool are different limits. L2 is a whole-device cache; do not list it as a per-SM resource. Likewise distinguish FP32, FP64, and matrix execution resources before comparing architectures. Hopper resource limits.
22. Suggested Projects (in order)¶
| # | Project | Key Skills |
|---|---|---|
| 1 | Vector add / SAXPY | Launch config, indexing, bounds check, H↔D copy |
| 2 | Parallel reduction (sum) | Shared memory, __syncthreads, tree reduction, warp shuffles |
| 3 | 2D grayscale transform | 2D threadIdx/blockIdx, image stride |
| 4 | Matrix transpose | Shared memory, bank conflict padding |
| 5 | Naive matmul → tiled matmul | Tiling, shared mem reuse, compare vs cuBLAS |
| 6 | Histogram | Atomics, per-block private histogram, reduce-merge |
| 7 | Prefix scan | Blelloch scan, upsweep/downsweep in shared mem |
| 8 | Multi-stream pipeline | Streams, async copy, overlap compute + transfer |
Keep CPU golden references for every kernel. Validate before optimizing.
Resources¶
| Resource | What it covers |
|---|---|
| CUDA C++ Programming Guide | The authoritative reference — thread hierarchy, memory, streams, graphs |
| CUDA C++ Best Practices Guide | Optimization strategies, memory patterns, profiling |
| NVIDIA Nsight Compute | Kernel profiler — roofline, memory, warp stats |
| NVIDIA Nsight Systems | System profiler — CPU/GPU timeline, stream overlap |
| Hopper Architecture In-Depth | H100 SM, TMA, FP8, Thread Block Clusters |
| Ampere Architecture In-Depth | A100 SM, MIG, sparsity, TF32 |
| CUDA Samples | Reference implementations: reduction, matmul, scan |
| Programming Massively Parallel Processors (Hwu, Kirk, Hajj) | GPU architecture + CUDA optimization textbook |
Next¶
→ OpenCL and SYCL — portable compute across vendors.
Optimize under a verified kernel contract¶
Use the CPU corpus to validate the reduction and tiled matrix product, including N=0, ragged sizes, and large/small magnitudes. Respect each example’s launch assumptions. Run memory/race checks where the installed tooling supports them; synchronization-free warp code is not made correct by volatile.
Change one factor—tile dimensions, shared layout, or streams—and compare output tolerance, register/shared-memory use, measured bytes, and latency. Keep a host trace beside kernel counters. Reuse the resulting shape/dtype/layout table when choosing compiler operators and accelerator instructions; do not design the ISA around one favorable benchmark shape.
Carry forward: Verified kernel plus a profiler-backed explanation of one optimization. Continue with the next course and reuse that evidence.