Hardware-Aware LLM Quantization and Inference Optimization
Learn to choose and evaluate a precision policy using numerical error, actual storage, runtime support and task behavior. Start with the CPU exercise; a GPU is needed only for the optional native-kernel performance extension.
Layer mapping: numerical representation, compiler/kernel dispatch and serving (L4–L6). Roles: inference systems, model compression, GPU runtime and efficiency research engineering. Artifact: a reproducible calibration and policy report with a storage ledger, held-out results and explicit execution limits.
Begin here
You need matrix multiplication, basic probability, Python and PyTorch inference. Use the quality-metrics lab for masked NLL/KL, and Phase 4 quantization for scale/granularity vocabulary. CUDA profiling is required for the device route, not for the CPU learning path.
Entry diagnostic: does a smaller file guarantee faster inference? Does lower drafter acceptance mean lower target quality? Does a 64-layer hybrid model need 64 layers of ordinary K/V history? The answer to each is no. Modules 01, 08 and 09 explain the missing conditions.
Allow 20–40 minutes for dependency setup if needed, 30–60 minutes for the CPU lab and analysis, then 8–12 focused study hours for the modules and capstone. The small CPU experiment executes in seconds on the tested host; hardware setup and model evaluation have separate, workload-dependent costs.
Evidence and the case study
Source Evidence pins the official Qwen3.8-27B config and two community quantized artifacts. The target has 16 full-attention plus 48 linear- attention layers, hidden size 5120 and vocabulary 248320. The current community export quantizes its output head and removes built-in MTP; its external DSpark drafter is a separate model. The model-card measurements are publisher-reported, not reproduced by this course. Metadata checks and the small PyTorch lab were executed locally; no 27B weights or GPU kernels were executed for this review.
Task quality, reference fidelity and draft efficiency have separate metrics. Acceptance cannot replace labeled task tests, and a byte ledger cannot replace hardware traffic measurements. Every numerical worked example states which values are analytical, synthetic or source-reported.
Course map
| Lesson | Learn | Produce |
|---|---|---|
| 01 — Inference physics | roofline assumptions, units and traffic | annotated latency estimate |
| 02 — Quantization mathematics | E2M1, scales, rounding, storage | a block calculation and payload ledger |
| 03 — Blackwell hardware | SM100/SM120, W4A16/W4A4, compatibility | evidence for one kernel path |
| 04 — Model anatomy | actual config, serialized bytes versus reads | metadata-backed model ledger |
| 05 — Calibration | clipping objectives, data splits, AWQ/GPTQ/SmoothQuant | calibration ablation |
| 06 — Activation outliers | scaling axes and measured outlier structure | an activation profile |
| 07 — Sensitivity | cancellation, softmax, RoPE and task effects | one-group and joint-error tests |
| 08 — Behavior | task, fidelity and acceptance distinctions | correctly normalized metric report |
| 09 — KV and hybrid state | GQA, recurrent state, capacity/traffic crossover | context feasibility table |
| 10 — Speculation | exact correction and complete cycle cost | categorical proof or device K sweep |
| 11 — Precision allocation | constrained search and nonadditive errors | exact small search and greedy counterexample |
| 12 — Measurement | paired runs, uncertainty and provenance | reproducible experiment record |
| 13 — Capstone | assemble and challenge the policy | reusable evaluator and report |
Read the storage before selecting the kernel
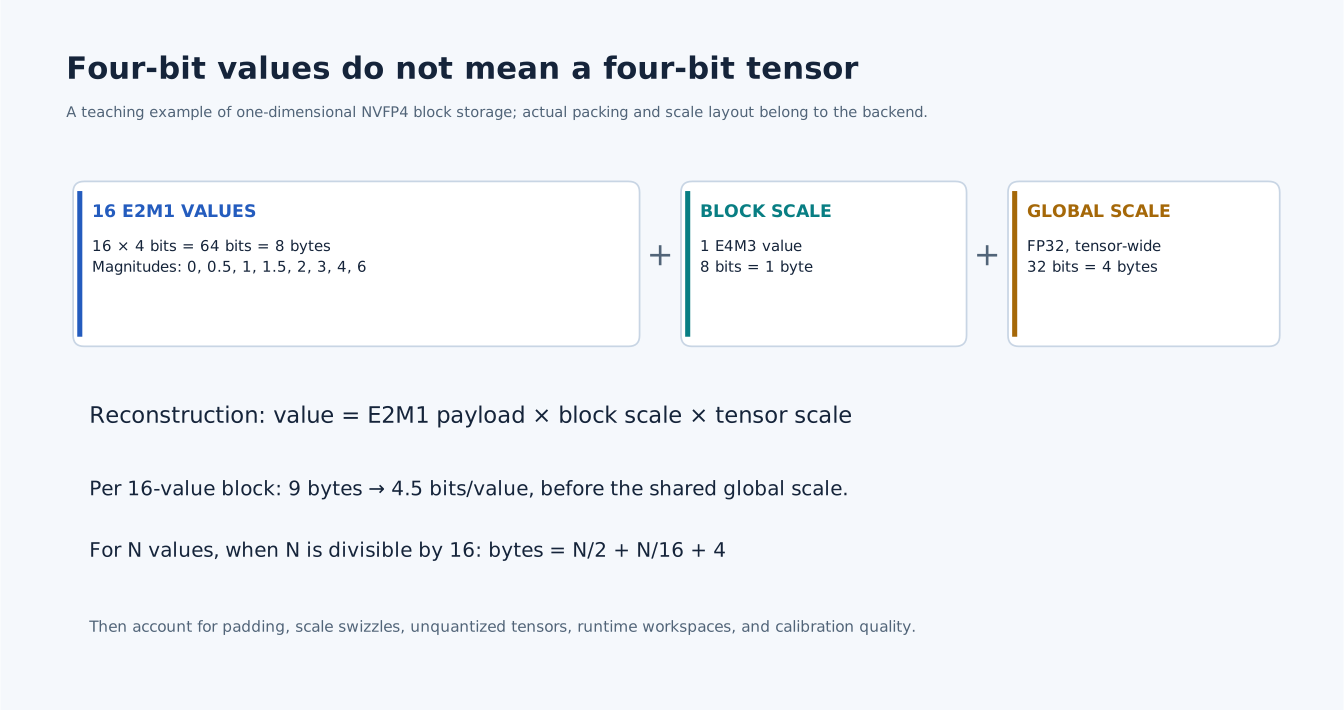
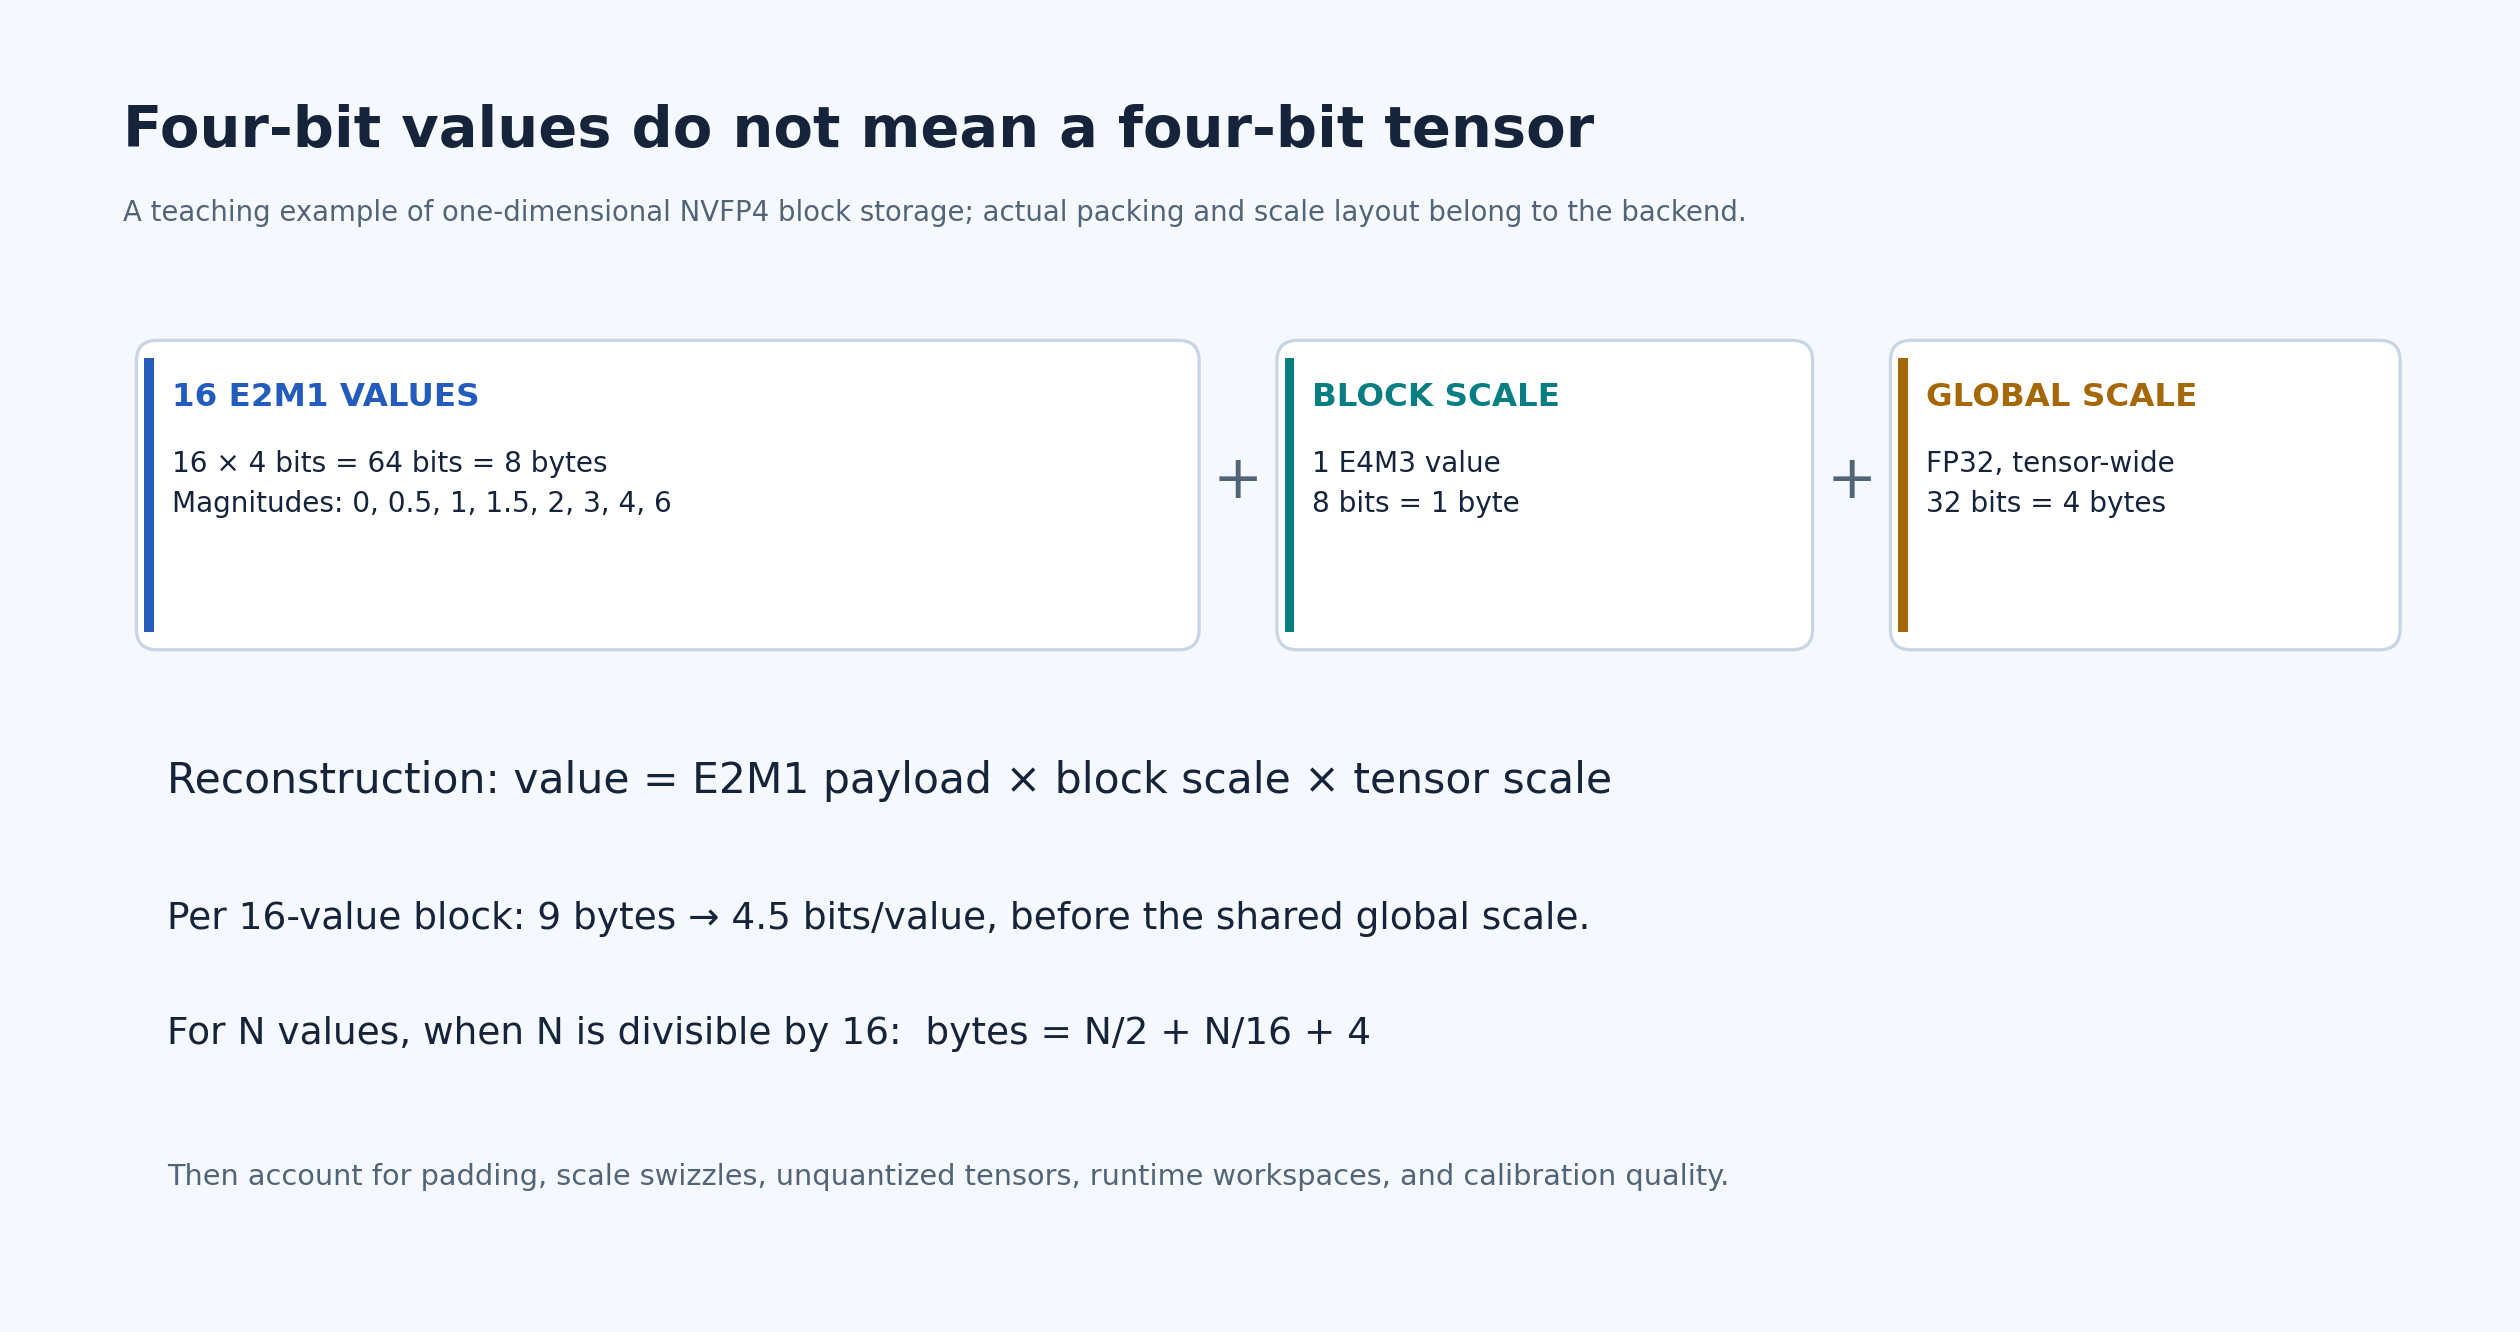
Derive the 2308-byte storage of 4096 values in this stated 1D layout before padding. Identify which metadata a custom compiler must preserve. Download PNG.
Run, vary, explain
The CPU Quantization Lab trains the existing small robot-stop network, packs reference FP4 weights using real PyTorch E4M3 scale casts, compares calibration objectives, reloads the packed artifacts, and tests clean and biased-sensor episodes. Portable tests also check hybrid KV accounting, correct speculative mass and a greedy-allocation counterexample.
The packed layout is a teaching format. CPU execution dequantizes weights to float32; its timings would not establish native FP4 acceleration. Use the pinned runtime/hardware contract in Module 03 for any device extension.
Completion
Pass the tests, explain one failed assumption, and submit payload, calibration, task and fidelity results with their sources. Demonstrate that test data did not select the quantizer. State the quality budget before choosing a deployment policy; retaining the reference is valid when candidates fail it.
Use the shared study cycle: predict a result, run one controlled variation, explain a failure, then repeat the self-check after two days. Continue with TVM Deep Dives to carry the precision contract into a compiler, or Inference Part 4 for engine-level measurement.
Carry this course into the physical-AI system
Start from: A supported checkpoint/kernel format and a higher-precision reference.
Build and challenge: Derive packed bytes including scales and unchanged tensors. Pair each precision change with quality and dispatch evidence; combine optimizations only after measuring them individually.
Pass forward: A precision/layout contract with error budgets for the compiler and accelerator. Continue with the connected course and keep the artifact in the Physical AI Design Studio.