VLA optimization and action-parity harness
Optimize a robot policy while preserving its action meaning, timing contract, and task behavior. Begin with a small policy you can actually train and inspect; then apply the same evidence requirements to a named VLA checkpoint.
Prerequisites: the CPU policy, timed robot loop, and VLA action contracts. Learn quantization before the optional GPU extension. Roles: robot learning, inference, controls, and evaluation engineers. Hardware layers: model → runtime → middleware → controller.
A connected route with two evidence levels
| Session | Work | Artifact |
|---|---|---|
| 1, 60–90 minutes | Optimize the actual policy path | Action contract, architecture-specific optimization hypothesis, explicit timing boundary |
| 2, 60–90 minutes | Build an honest parity gate | Numerical, trajectory, task and statistical acceptance rules |
| 3, 90–120 minutes | Run the CPU action-parity bridge | Trained reference, seven candidate cases, retained failure evidence and JSON report |
| Extension, target dependent | Apply the protocol to one supported pretrained policy and simulator | Pinned checkpoint/runtime, raw traces, actual device measurements and held-out outcomes |
The supplied CPU lab reuses and trains the Phase 3 model, then calls the same cart timing environment. It compares an algebraic normalization fold, rounded weights, a missing-normalization fault, and changed queue/deadline settings. It is a functioning learning/evaluation experiment, without an image encoder, language input, pretrained VLA, integer inference kernel, or physical robot.
The GPU extension is a separate milestone. Source-checked APIs do not mean a checkpoint or runtime has been executed here. The 32-lesson companion provides architecture, training, dataset and deployment depth.
Four questions that need separate answers
- Semantics: do observation order, normalization, action units, frames, timestamps, chunk spacing and reset state still agree?
- Numerics: on the same recorded inputs and compatible random draws, how do decoded physical actions differ before and after limits?
- Behavior: under paired initial conditions, what changes in trajectories, applied observation age, failures and task success?
- Evidence strength: does the sample support the stated population claim, or only a regression result for this fixed suite?
A candidate can pass one question and fail the next. The CPU example with the same weights and a slow FIFO has zero action discrepancy on saved inputs but loses all twelve reference successes. Another candidate reaches the same twelve terminal goals but exceeds this fixture's declared trajectory-difference limit. The result is more informative than one combined score.
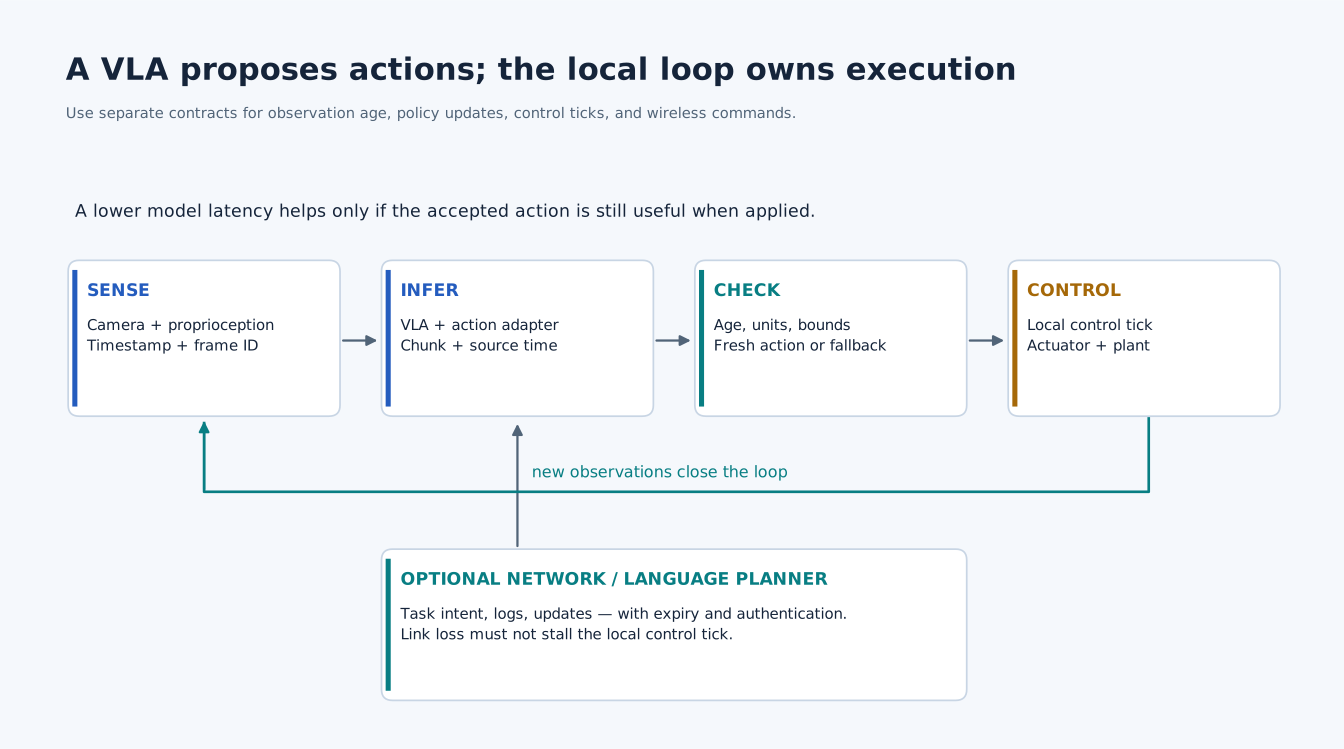
Start the executable bridge
From the repository root, with Python 3.12 and no third-party packages:
python3 'Phase 5 - Advanced Topics and Specialization/Track D - Robotics/VLA Optimization and Action-Parity Harness/labs/action_parity.py' --output /tmp/action-parity-report.json
python3 -m unittest discover -s 'Phase 5 - Advanced Topics and Specialization/Track D - Robotics/VLA Optimization and Action-Parity Harness/labs' -p 'test_*.py' -v
Keep the full checkout: this lab imports the actual Phase 3 policy and timing modules using paths relative to its own file. Downloading only this script is insufficient. The lab guide explains every reported candidate and the gate's exit codes.
What the optional VLA extension must freeze
Choose a checkpoint intended for the selected task and embodiment. Save its weight revision, preprocessing, tokenizer if used, normalization statistics, action adapter, policy RNG/reset behavior, runtime, simulator and asset versions, and evaluation episode list. A generic base policy is not automatically a LIBERO policy, and a supported language backbone does not establish support for the complete multimodal/action graph.
As reviewed on 18 October 2026, OpenVLA exposes an action-specific API and normalization selection; openpi applies input/output transforms around action sampling; GR00T has its own deployment paths. The source manifest pins the inspected revisions. Read the architecture-specific discussion in lecture 1 before replacing those paths with a generic LLM server.
Submit the model/adapter manifest, one controlled optimization, raw numerical and timing traces, paired episode outcomes, a caught fault, and an explicit claim boundary. A CPU milestone can pass without GPU or robot access. A physical deployment claim requires the separate target and task validation it names. Use the shared rubric, then carry verified operator shapes and traces into the Physical AI Design Studio.